Who Pays for the KV Cache? Attributing Shared AI Inference Spend Across Kubernetes and LLM Provider Bills
KV 캐시 비용은 누가 내는가? — 쿠버네티스·게이트웨이·프로바이더 청구서를 하나의 장부로 TL;DR — 같은 AI 기능 한 건에 드는 비용은 쿠버네티스 할당, 게이트웨이 로그, 프로바이더의 토큰 단위 청구서라는 서로 연결되지 않은 세 장부에 흩어져 있다. 저자는 이 세 장부를 하나의 Decimal-정확…
![[논문 리뷰] Hardware-Efficient Attention for Fast Decoding](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/hardware-efficient-attention-for-fast-decoding-1.png)
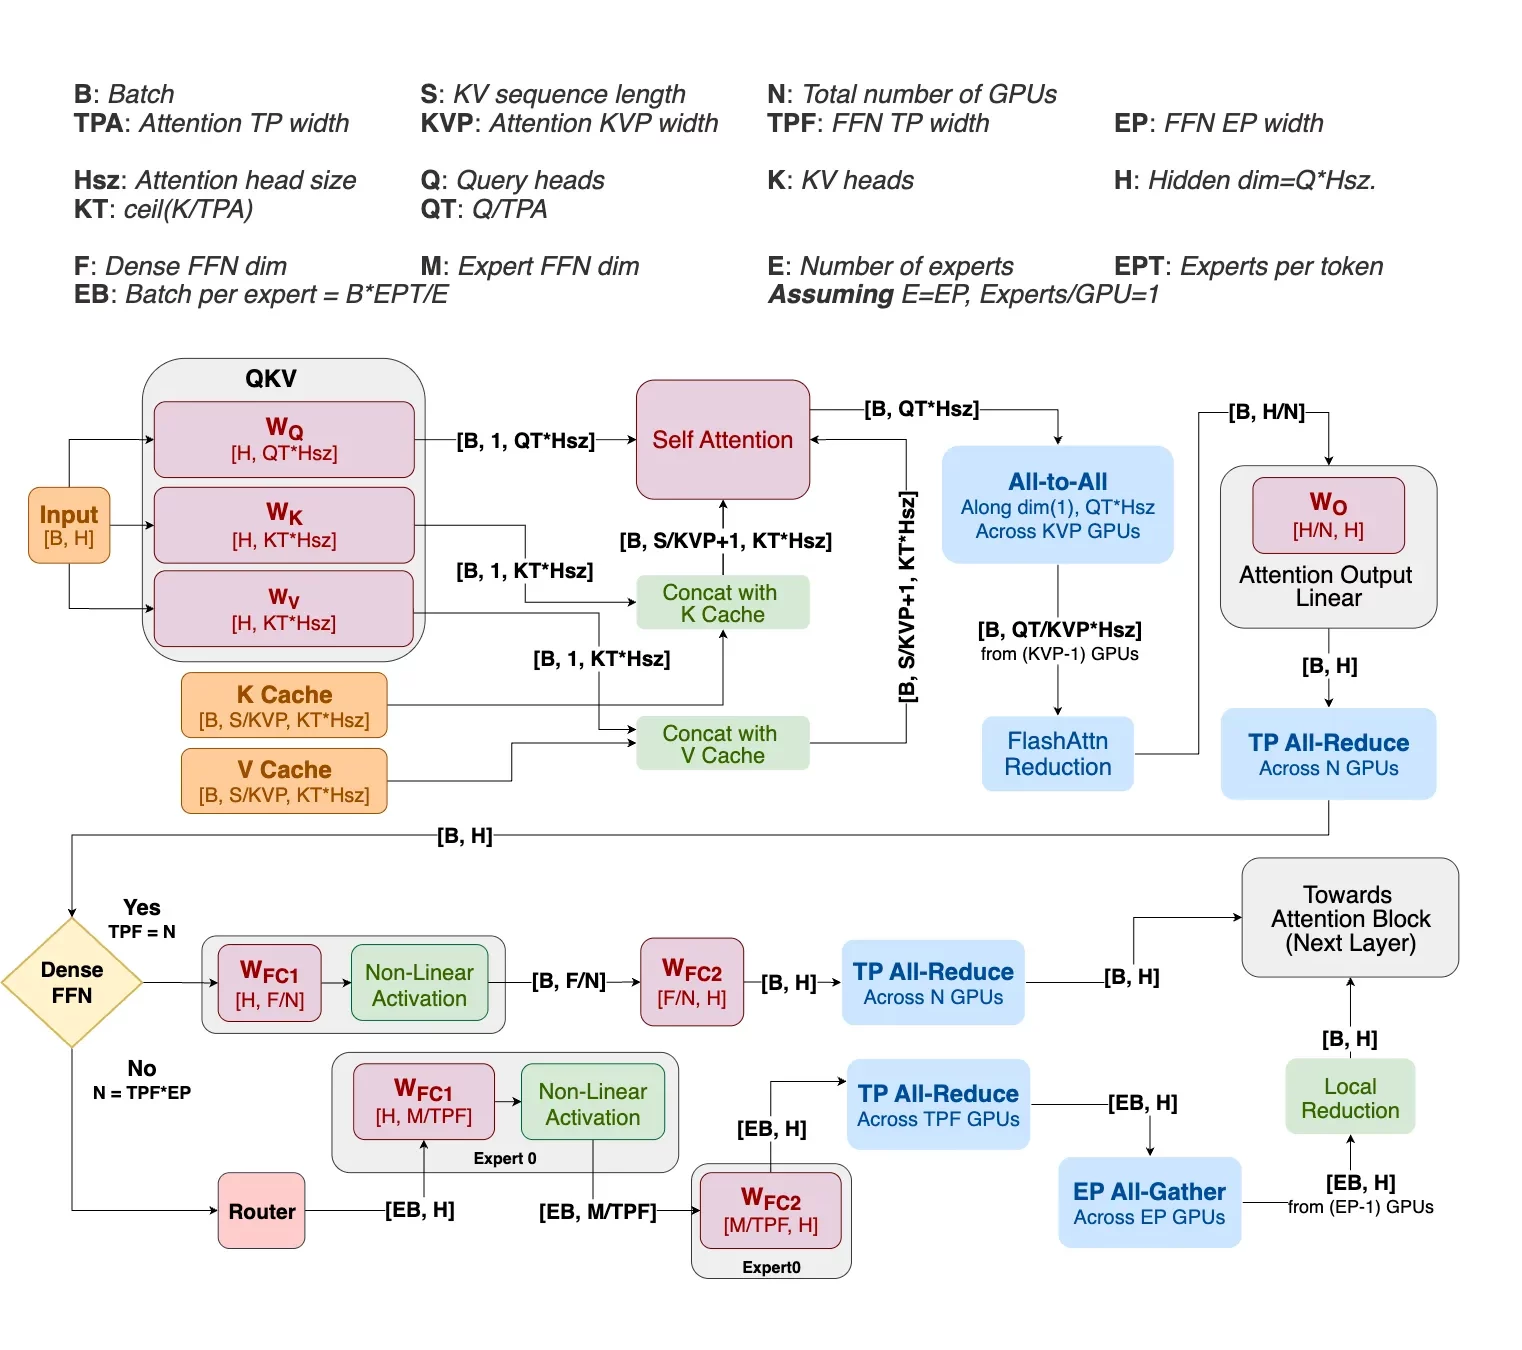
![[논문리뷰] Helix Parallelism: Rethinking Sharding Strategies for Interactive Multi-Million-Token LLM Decoding](https://www.storagereview.com/wp-content/uploads/2025/07/image2-2-png-e1752234784623.webp)