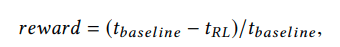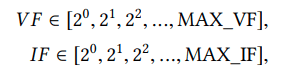
NeuroVectorizer 프레임워크 개요 도식의 축소판

제목

NeuroVectorizer: End-to-End Vectorization with Deep Reinforcement Learning

저자

Ameer Haj-Ali, Nesreen K. Ahmed, Ted Willke, Sophia Shao, Krste Asanovic, Ion Stoica

Motivation

Compilers are designed today to use fixed-cost models that are based on heuristics to make vectorization decisions on loops. However, these models are unable to capture the data dependency, the computation graph, or the organization of instructions The vectorization is critical to enhancing the performance of compute-intensive workloads in modern computers.

Contribution

A comprehensive data set of more than 10,000 synthetic loop examples. An end-to-end deep reinforcement learning (RL) based auto loop-vectorization method

개인적인 느낌

search space가 너무 작아서 솔찍하게 의미가 있는지 의문.. /

The Proposed Framework Architecture
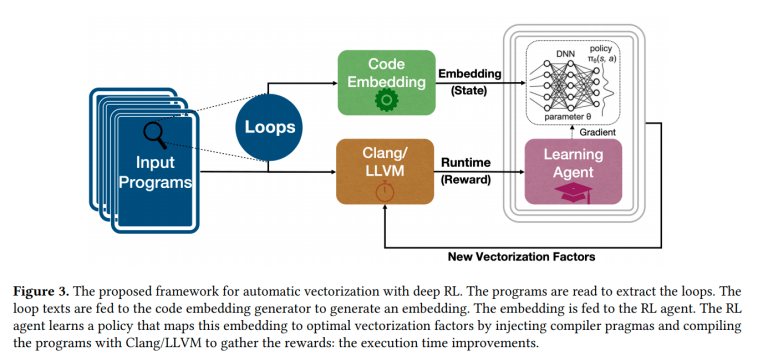
Figure 3: 자동 벡터화를 위한 심층 강화학습 프레임워크. 입력 프로그램에서 루프를 뽑아 코드 임베딩을 만들고, 그 임베딩을 상태로 받은 RL 에이전트가 벡터화 인자를 정해 Clang/LLVM 으로 컴파일한 실행 시간을 보상으로 되돌려 받는다

Code Embedding

  • Code2vec(Embedding Network) represents a code snippet as a single fixed-length code vector, which can be used to predict the semantic properties of the snippet.
  • This vector captures many characteristics of the code, such as semantic similarities, combinations, and analogies
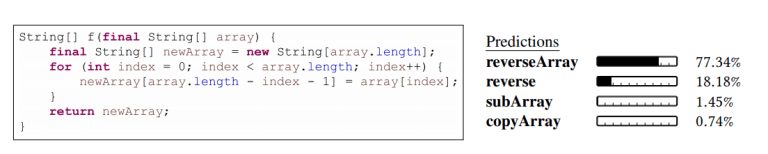
자바 배열을 뒤집는 함수 코드와 그 예측 결과. reverseArray 77.34%, reverse 18.18%, subArray 1.45%, copyArray 0.74% 로 막대가 그려져 있다
A code snippet and its predicted labels as computed by code2vec reference
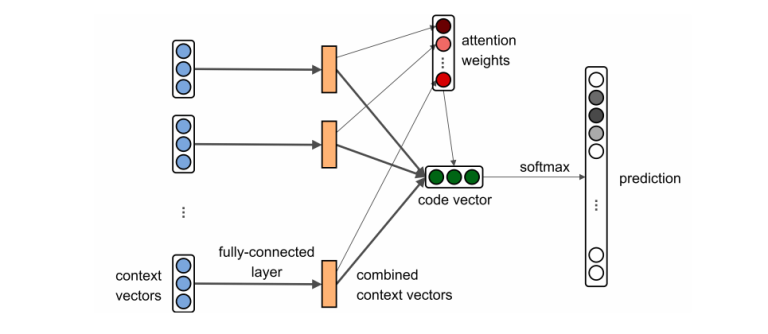
path-attention 신경망 구조. 여러 컨텍스트 벡터가 완전연결 층을 거쳐 어텐션 가중치로 합쳐져 하나의 code vector 가 되고, softmax 를 통해 예측이 나온다
The architecture of our path-attention network. A full-connected layer learns to combine embeddings of each path-contexts with itself; attention weights are learned using the combined context vectors, and used to compute a code vector. The code vector is used to predicts the label. reference

Automatic Vectorization Example

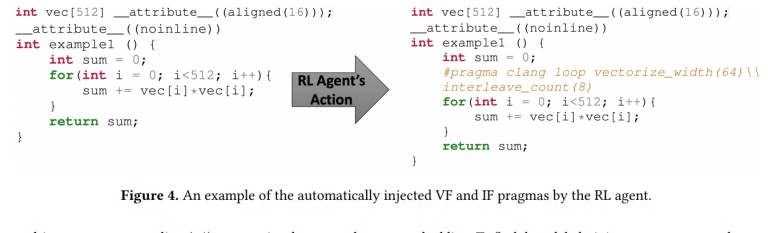
Figure 4: RL 에이전트가 pragma 를 자동으로 끼워 넣은 예. 왼쪽 원본 루프에 오른쪽처럼 #pragma clang loop vectorize_width(64) interleave_count(8) 이 삽입되어 있다

The RL Environment Definition

보상 정의 수식. reward = (t_baseline − t_RL) / t_baseline
where baseline is the execution time when compiled with the currently implemented baseline cost model in LLVM and RL is the execution time when compiled with the injected pragmas by the RL agent
행동 공간 정의 수식. 벡터 폭 VF 와 인터리브 수 IF 가 각각 2의 거듭제곱으로 MAX_VF, MAX_IF 까지의 값을 갖는다
where MAX_VF and MAX_IF are respectively the maximum VF and IF supported by the underlying architecture

Dataset Description

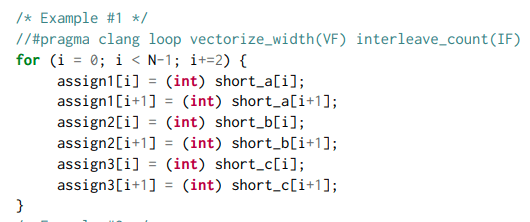
데이터셋 예시 코드. vectorize_width(VF) 와 interleave_count(IF) pragma 가 주석 처리된 이중 전개 루프에서 short 배열 세 쌍을 int 로 대입한다
To speed up the training, and make it more efficient, we built a dataset that includes loops only. We built generators that generate more than 10,000 synthetic loop examples automatically from the LLVM vectorization test-suite.

Handling Long Compilation Time

  • During training, some of the programs took a long time to compile, mainly when the agent was trying to vectorize more than plausible
  • giving a penalty reward of −9 (equivalent to assuming it takes ten times the execution time of the baseline) so that the agent will learn not to overestimate the vectorization and avoid it

Results:Reward mean and training loss for different action space definitions
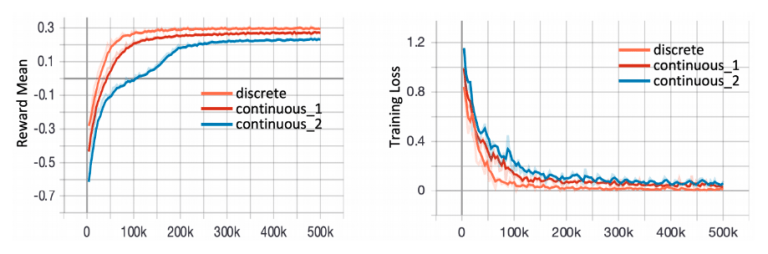
학습 곡선 두 개. 왼쪽은 보상 평균, 오른쪽은 학습 손실이며 discrete, continuous_1, continuous_2 세 설정이 50만 스텝에서 수렴한다

Results:The performance of the proposed vectorizer
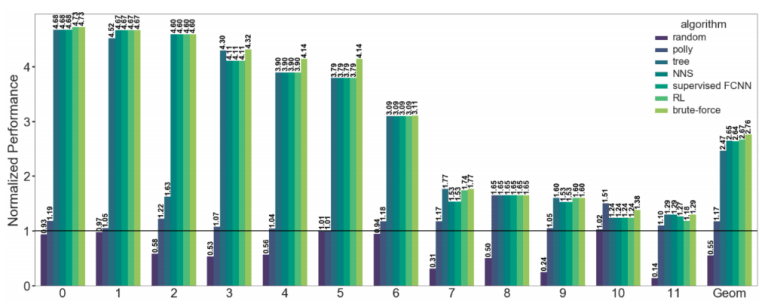
벤치마크 12개에 대한 정규화 성능 막대그래프. random, polly, tree, NNS, supervised FCNN, RL, brute-force 를 비교했고 기하평균에서 RL 2.67 로 brute-force 2.76 에 근접한다
The performance is normalized to the baseline(VF = 4, IF = 2)

Results:Normalized average performance of supervised FCNN and deep RL
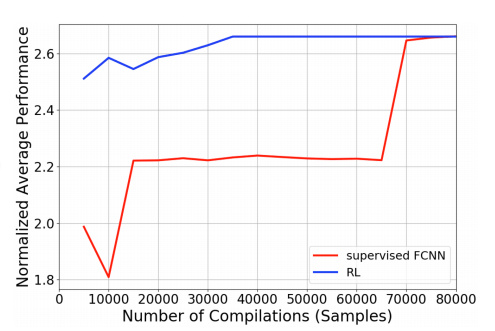
컴파일 횟수에 따른 정규화 평균 성능 선그래프. RL 은 3만 5천 회 부근에서 2.66 에 도달하는 반면 supervised FCNN 은 7만 회를 넘겨야 같은 수준에 이른다

Results:The performance of the proposed vectorizer on
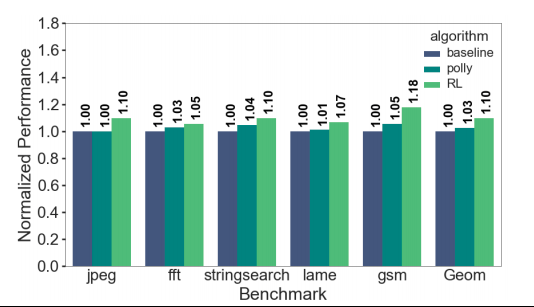
Mibench 벤치마크(jpeg, fft, stringsearch, lame, gsm)에서 baseline, polly, RL 의 정규화 성능 막대그래프. RL 기하평균 1.10 으로 polly 1.03 보다 높다
Mibench compared to Polly and the baseline cost model

The performance is normalized to the baeline(VF = 4, IF = 2)

references

https://arxiv.org/abs/1909.13639

라이선스

작성자: Jaehun Ryu

링크: https://jaehun.me/posts/%EB%85%BC%EB%AC%B8-%EC%A0%95%EB%A6%AC-neurovectorizer-end-to-end-vectorization-with-deep-reinforcement-learning-cgo-20/

라이선스: CC BY 4.0

이 저작물은 크리에이티브 커먼즈 저작자표시 4.0 국제 라이선스에 따라 이용할 수 있습니다. 출처를 밝히면 상업적 목적을 포함해 자유롭게 이용 가능합니다.

댓글