제목
TVM: An Automated End-to-End Optimizing Compiler for Deep Learning
TVM?
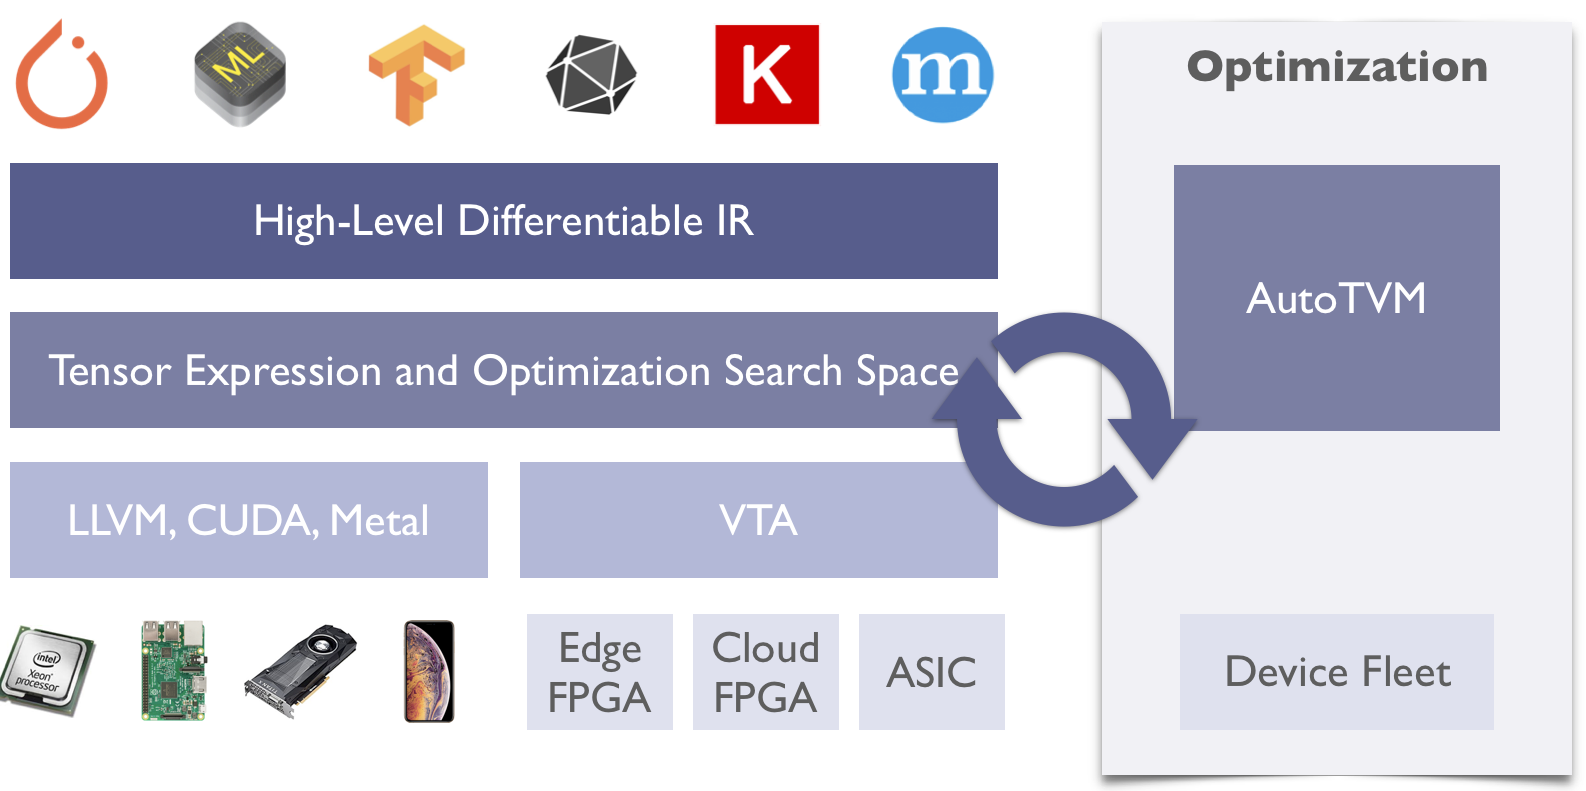
해당논문은 머신러닝용 컴파일러중에 대표적인 TVM에 대한 paper입니다. 현재는 apache에서 관리 하고 있으며 graph level IR 을 통한 target-independent optimization, autotune을 통한 target-dependent optimization 을 지원하며 llvm 및 vta를 통하여 cpu,gpu뿐만 아니라 FPGA를 backend로 지원합니다.
저자
Tianqi Chen and Thierry Moreau, University of Washington; Ziheng Jiang, University of Washington, AWS; Lianmin Zheng, Shanghai Jiao Tong University; Eddie Yan, Haichen Shen, and Meghan Cowan, University of Washington; Leyuan Wang, UC Davis, AWS; Yuwei Hu, Cornell; Luis Ceze, Carlos Guestrin, and Arvind Krishnamurthy
Motivation
기존 머신러닝을 이용한 compiler optimizaion 방법에서는 human experts를 이용한다양한 hardward back-end(GPU,FPGA,ASIC)이 늘어남에 따라 그 구조에 적합한 complier optimization이 달라 질 수 밖에 없다.
Contribution
해당논문은 머신러닝 High level Graph 연산을 ML 기반으로 특정 device 적합한 excutable 코드를 만들도록 수행하는 방법을 제시. 전체적인 framework의 blueprint 느낌이 강하고 전형적인 DL compiler의 구조라서 큰 contribution을 느끼지는 못함.
Content
Graph level modification & hareware-aware optimization
- Operator Fusion
- Combines many small ops
- Constant Folding
- Pre-computes static graphs
- Static Memory Planning Pass
- Pre-allocates memory for needed tensors
- Data Layout Transformations
- Optimize data storage for each backend
- cost model에 ML을 이용
- Query에서 추출한 feature 를XGBoost 를 이용하여 costs 를 예측
references
https://arxiv.org/abs/1802.04799
댓글