Contextual Correction of Parallel Drafts for Speculative Decoding
DCOCO reselects existing parallel draft candidates using contextual scores. This review distinguishes accepted length from actual throughput and examines correction…
DCOCO reselects existing parallel draft candidates using contextual scores. This review distinguishes accepted length from actual throughput and examines correction…
Fixed-point behavior connects KV sharing, state reuse, and distilled prefill in looped language models. We review the savings and accuracy trade-offs demonstrated on…
TokenRouter: An Efficient Serving System for Token-Level LLM Routing TL;DR — Routing an LLM at the token level rather than the session/query level can substantially push…
Mechanics of Long-Context Hybrid Models: From Hybrid Attention to Hybrid Position TL;DR — These days open-source LLMs are rapidly shifting from models that "use full…
SlimKV: Compressing Tokens and Features Together, Cutting the KV Cache by up to 32× with Reconstruction-Free Latent-Space Attention TL;DR SlimKV is a question-agnostic…
Phase Sensitivity: The 'Periodic Weakness' Created by Chunked KV-Cache Compression TL;DR — In models that use chunked KV-cache compression (such as the DeepSeek-V4…
Paper MassAlloc Attention (MALA): Letting Attention Allocate Its Own Compute TL;DR — Full softmax attention (FullAttn) performs all post-score computation after QK score…
SPECTRA: A Reconfigurable LLM Accelerator That Changes Its Hardware With Every Inference Stage TL;DR Speculative decoding oscillates between prefill (compute-bound GEMM),…
ActionPiece: Rethinking Action Tokenization Beyond Reconstruction Error, via Physical Ranking TL;DR — In autoregressive VLA (vision-language-action) models, the action…
StepAudio 3 Gen: Unifying Speech, Song, Music, and Sound Effects with a Single Discrete Autoregressive (RVQ) Model TL;DR StepAudio 3 Gen, released by StepFun, is a fully…
SAS: A Simple Attention Sparsification That Learns Context Ranking Directly Without Distillation TL;DR — In post-training attention sparsification, inject the continuous…
Marigold V2: Reviving an Image-Editing Diffusion Transformer (DiT) as a Monocular Depth Estimator TL;DR This study fine-tunes an image-editing diffusion transformer…
SQS: Fusing Pruning and Quantization into One Bayesian Learning — Where Spike-and-Slab Meets GMM TL;DR — Doing pruning and low-bit quantization separately leaves…
X-AuT: Pruning Audio Encoders in Speech LLMs with Behavioral Probes and Cross-Scale Distillation TL;DR X-AuT is a framework that progressively prunes the audio encoder…
Deadline-Filling Prefill Chunks: SLOWeave — An Adaptive Chunking Scheduler for LLM Serving TL;DR — Instead of a fixed prefill chunk size, we propose SLOWeave, an online…
SMELT: Scaling Laws for Compute-Matched MoE Loop Transformers TL;DR Loop transformers scale depth by executing a layer block repeatedly, but most prior work fixed only…

Structured State Space Duality: Unifying SSMs and Attention with Mamba-2 for 2–8× Acceleration TL;DR Structured State-Space Duality (SSD) reveals that SSMs and masked…
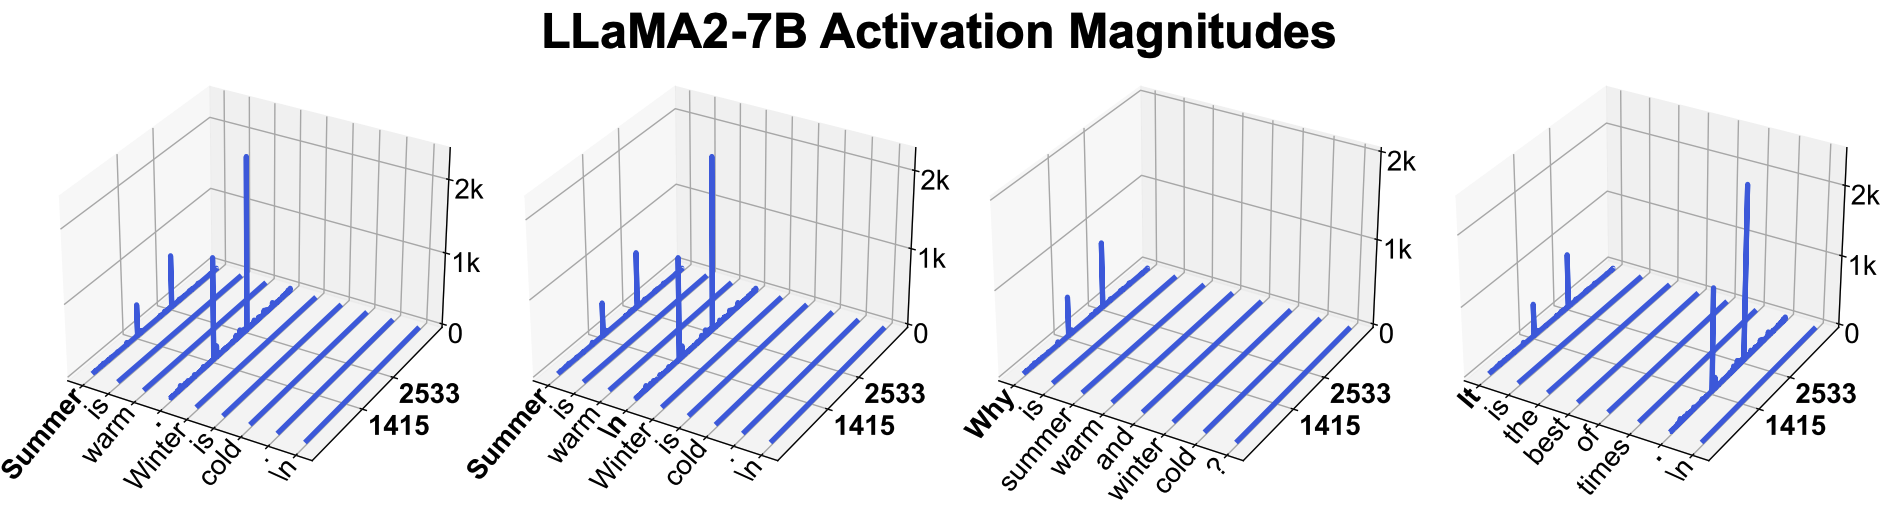
Massive Activations, Hidden Biases: A Reinterpretation of Self-Attention’s Secrets TL;DR Just 4–10 extreme scalar values (×10,000) out of tens of millions can…
CODE I/O: From Code I/O + Natural-Language CoT to General-Purpose Reasoning — Lifting 7B-30B LLMs by +2 Points on Average with Data Design Alone TL;DR A single data…