Channel Selection for Mixture-of-Experts Decoding Needs No Calibration Data
Introduction In settings where the batch size is close to 1, such as conversational services, the latency of a mixture-of-experts language model comes mostly from reading…
Introduction In settings where the batch size is close to 1, such as conversational services, the latency of a mixture-of-experts language model comes mostly from reading…
SparseDecoding calibrates pruning on model-generated tokens and adds a decoding-specific sparse kernel. We examine the conditions behind its maximum 1.48× speedup on A100…
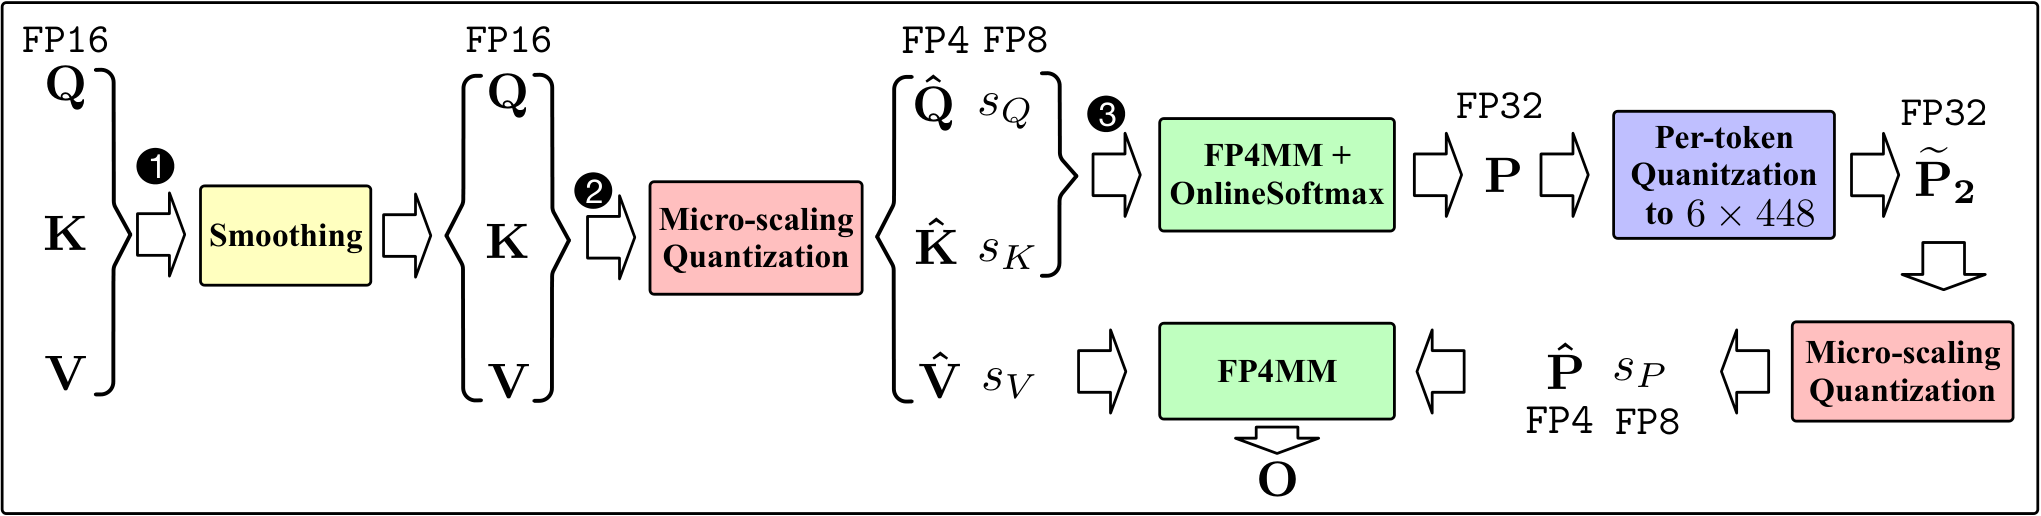
Separate SageAttention3 FP4 inference from SageBwd INT8 training, with checked examples of quantization error, storage overhead and kernel versus whole-workload speed.
Native Sparse Attention (NSA) — 11× faster even at 64k tokens, accuracy intact One-line summary (TL;DR) NSA combines a three-branch sparse attention — “compress → select…