Who Pays for the KV Cache? Attributing Shared AI Inference Spend Across Kubernetes and LLM Provider Bills
Who pays for the KV cache? — Kubernetes, gateway, and provider bills in one ledger TL;DR — The cost of a single AI feature is scattered across three disconnected ledgers:…
![[Paper Review] Hardware-Efficient Attention for Fast Decoding](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/hardware-efficient-attention-for-fast-decoding-1.png)
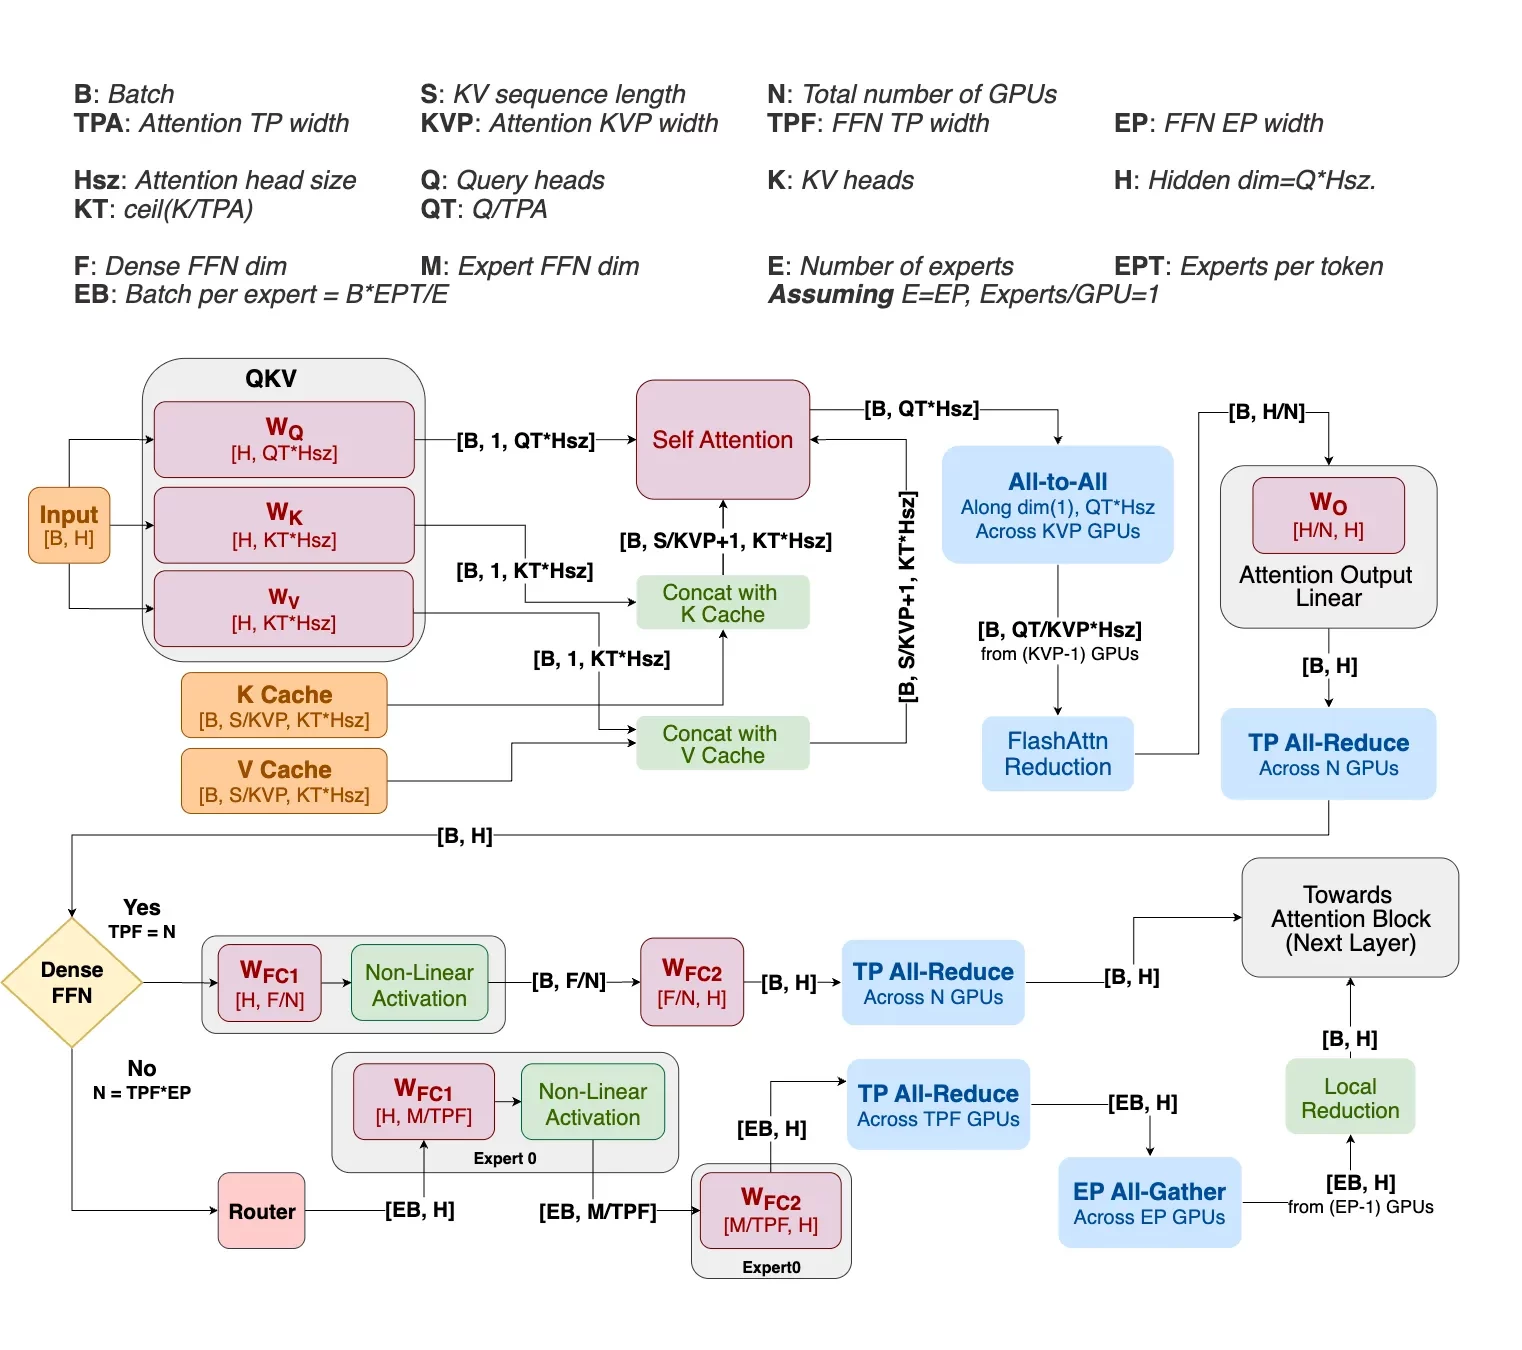
![[Paper Review] Helix Parallelism: Rethinking Sharding Strategies for Interactive Multi-Million-Token LLM Decoding](https://www.storagereview.com/wp-content/uploads/2025/07/image2-2-png-e1752234784623.webp)