FlashMask-3: Efficient and Expressive Mask-Aware Distributed Attention
An analysis of FlashMask-3’s Hopper kernels, mask localization, load balancing, communication overlap, and long-context training results and limitations.
An analysis of FlashMask-3’s Hopper kernels, mask localization, load balancing, communication overlap, and long-context training results and limitations.
MC-Sparse separates three sources of quality and efficiency loss in sparse DiT attention. This review explains why token selection and kernel execution costs must be…
Paper MassAlloc Attention (MALA): Letting Attention Allocate Its Own Compute TL;DR — Full softmax attention (FullAttn) performs all post-score computation after QK score…
WorldAttention: System Co-Design of an Interactive Video World Model That Drops the Sliding Window TL;DR — Text-controlled interactive video world models are trapped…
PISA: Pyramid Top-$K$ Selection Lowers the Cost of Block-Sparse Attention to $O(N\log N)$ TL;DR — Block-sparse attention makes attention computation linear, but block…
DeepSeek-V4.1-Flash: A Multimodal MoE That Cuts the KV Cache to 1/4 While Raising Performance Further TL;DR. DeepSeek-V4.1-Flash, released by DeepSeek-AI, is a multimodal…
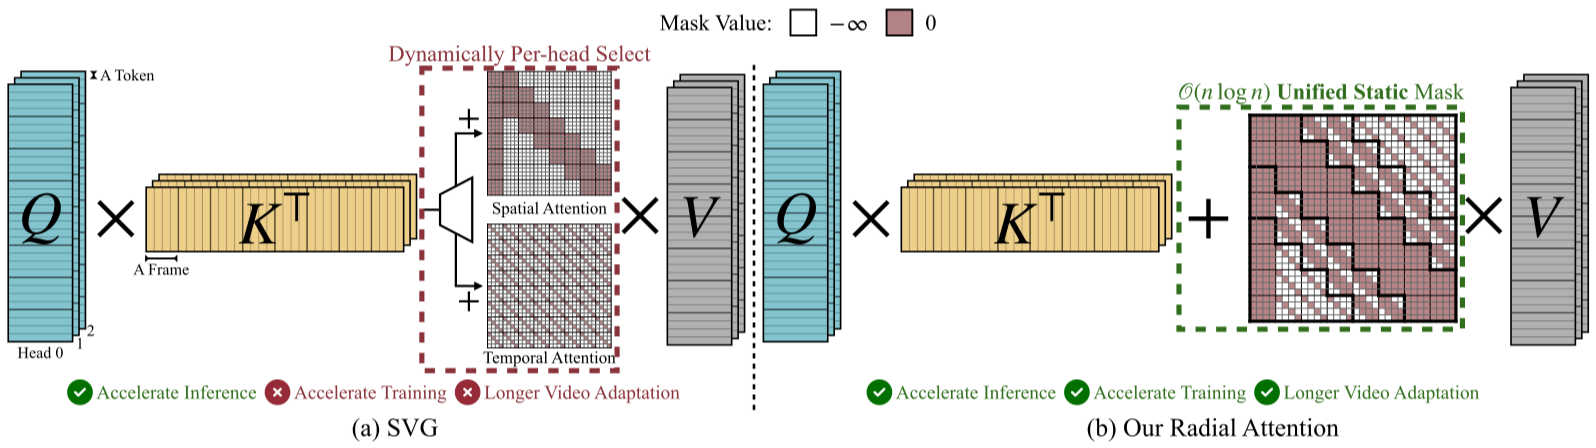
Radial Attention: O(n log n) Sparse Attention with Energy Decay — Generating "Long Videos" Cheaply One-Line Summary (TL;DR) Based on the observation that post-softmax…