Channel Selection for Mixture-of-Experts Decoding Needs No Calibration Data
Introduction In settings where the batch size is close to 1, such as conversational services, the latency of a mixture-of-experts language model comes mostly from reading…
Introduction In settings where the batch size is close to 1, such as conversational services, the latency of a mixture-of-experts language model comes mostly from reading…
Problem: Why It's Hard to Unify Understanding and Generation in One Representation There have been many attempts to merge image understanding and image generation into a…
TokenRouter: An Efficient Serving System for Token-Level LLM Routing TL;DR — Routing an LLM at the token level rather than the session/query level can substantially push…
TRACE: Rollout-Aligned FP4 Quantization-Aware Training — MoE LLM RL at BF16 Quality, up to 5.4x Faster TL;DR In reinforcement learning (RL) for MoE LLMs, quantizing…
DeepSeek-V4.1-Flash: A Multimodal MoE That Cuts the KV Cache to 1/4 While Raising Performance Further TL;DR. DeepSeek-V4.1-Flash, released by DeepSeek-AI, is a multimodal…
Waking the MoE on SSD: Serving a 35B MoE at 20 tok/s on a 24 GB Desktop with Edge0 One-line summary (TL;DR) Even at 4-bit, a 35B-class MoE occupies 19.5 GB and cannot…
Miles v0.1: A "verified, clean, and scalable" full-stack system for frontier RL post-training TL;DR: Miles is a full-stack RL post-training framework that resolves the…
Cache-Learning Routers: Cache-Aware Joint Router Adaptation for Memory-Constrained MoE Inference TL;DR Starting from the observation that MoE's real bottleneck is not…
SMELT: Scaling Laws for Compute-Matched MoE Loop Transformers TL;DR Loop transformers scale depth by executing a layer block repeatedly, but most prior work fixed only…

Engram: The Second Sparsity Axis After Conditional Computation (MoE), Conditional Memory One-Line Summary (TL;DR) Engram adds a "knowledge lookup primitive" to the…

NVIDIA Nemotron 3: Pushing the "Accuracy/Throughput" Frontier with a Hybrid Mamba–Transformer MoE Nemotron 3 combines an MoE hybrid Mamba–Transformer, LatentMoE, MTP,…

Qwen 3: The Evolution of a Giant MoE Language Model with Adjustable Reasoning Depth TL;DR (in one line) Qwen 3 couples a user-controllable Thinking Budget with a…
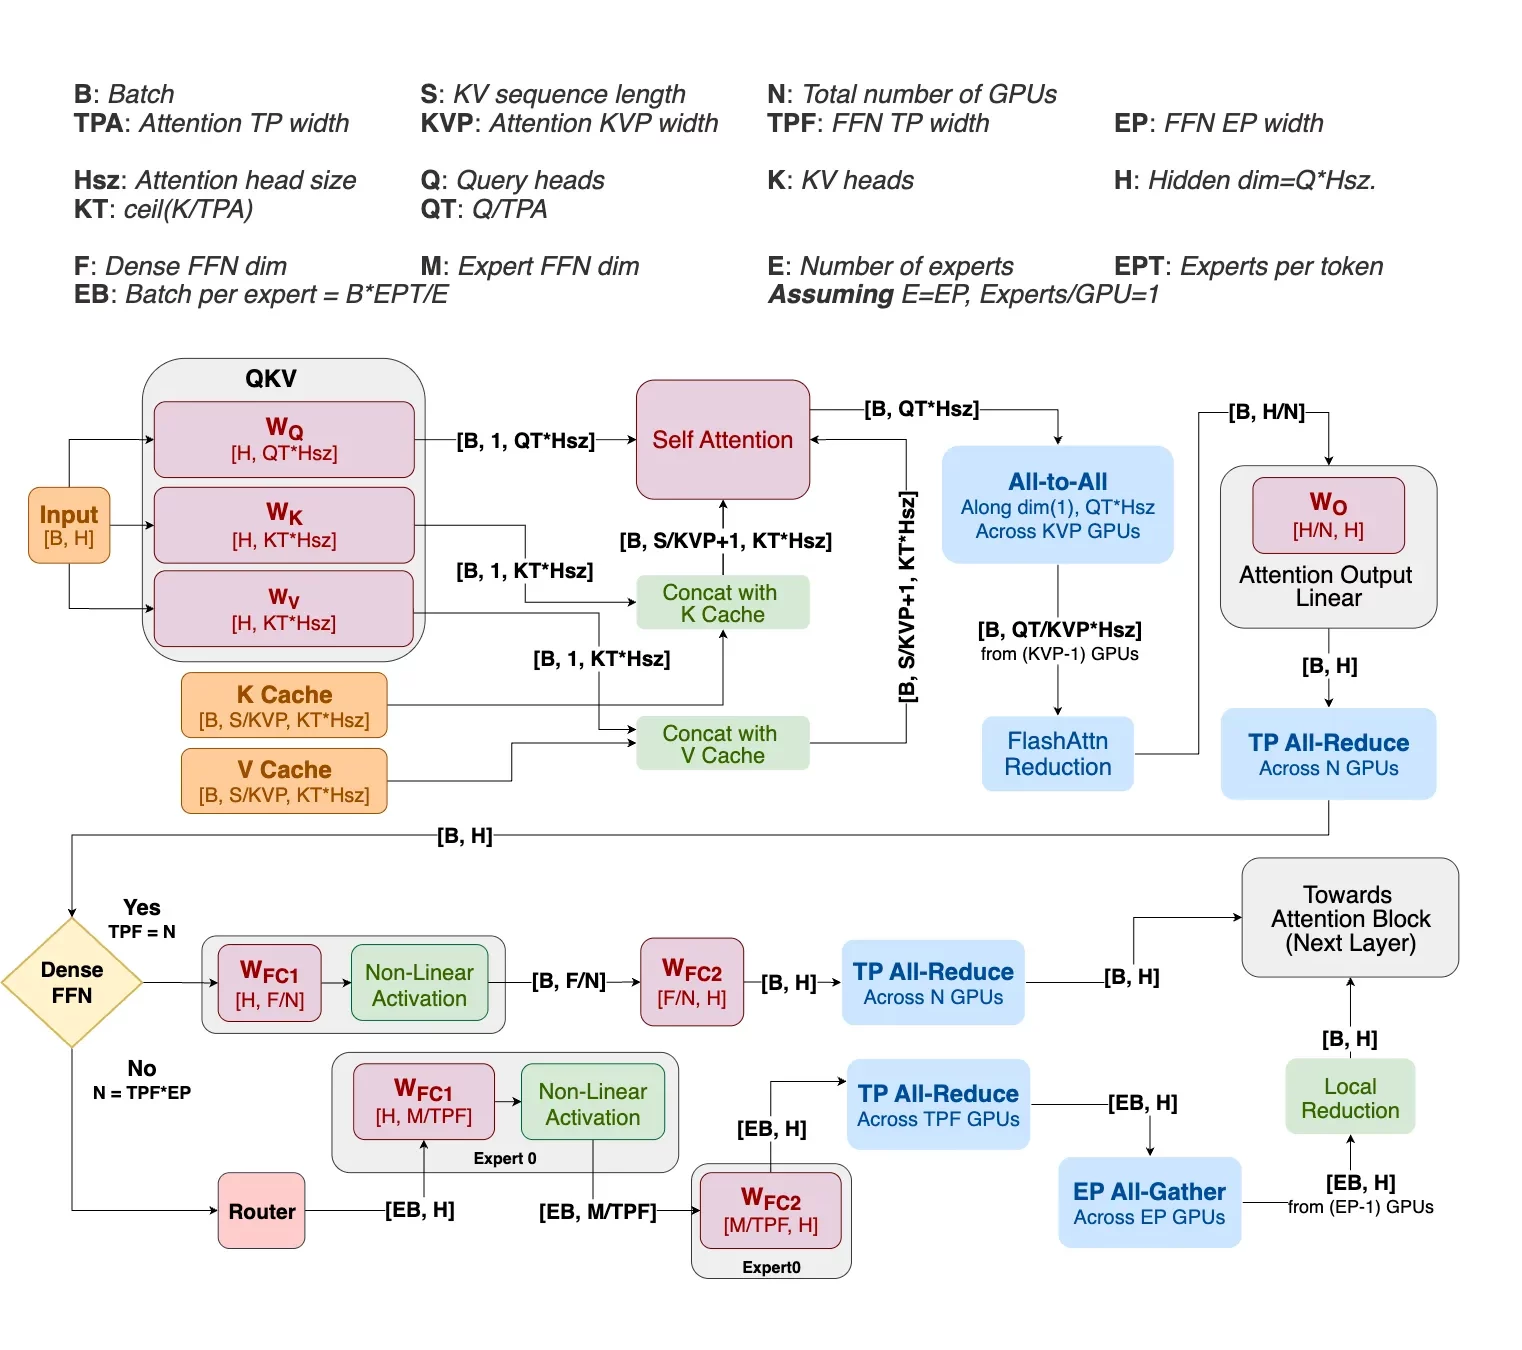
Helix Parallelism: Breaking the Latency-Throughput Wall of Ultra-Long LLM Decoding TL;DR Helix Parallelism schedules Attention and FFN with different parallelism…