MemT-1.0: Towards Memory-Native Evolution
MemT-1.0 stores conversation history in a fixed-size matrix state. We examine memory updates, information loss, and how the approach compares with full-context and…
MemT-1.0 stores conversation history in a fixed-size matrix state. We examine memory updates, information loss, and how the approach compares with full-context and…
On-Policy Is Not a Panacea: The Real Protagonists of Rollout Policy, KL Direction, and Learning Rate in Distillation Dynamics TL;DR — When we separate on-policy (OnPD)…
ActionPiece: Rethinking Action Tokenization Beyond Reconstruction Error, via Physical Ranking TL;DR — In autoregressive VLA (vision-language-action) models, the action…
Programmable World Model — Embedding "Executable State" into Generative Worlds One-Line Summary (TL;DR) Video world models are producing increasingly realistic…
Marigold V2: Reviving an Image-Editing Diffusion Transformer (DiT) as a Monocular Depth Estimator TL;DR This study fine-tunes an image-editing diffusion transformer…
SQS: Fusing Pruning and Quantization into One Bayesian Learning — Where Spike-and-Slab Meets GMM TL;DR — Doing pruning and low-bit quantization separately leaves…
X-AuT: Pruning Audio Encoders in Speech LLMs with Behavioral Probes and Cross-Scale Distillation TL;DR X-AuT is a framework that progressively prunes the audio encoder…
VestigeKV: The Degenerate RoPE Branch Carries Its Own Cache Eviction Signal TL;DR In NoPE-MLA models (Kimi Linear 48B), reading only 11% of each row — the 64-dim…
Uno: AR and Diffusion in One Model — Lossless Parallel Generation for LLM Acceleration TL;DR — LLMs are slow because next-token prediction (NTP) can emit only one token…
Catch the Moment a Model "Revisits Its Thoughts": How BeaconKV Compresses Reasoning KV Caches 5.8× with Beacon Queries TL;DR — The KV cache of a Large Reasoning Model…
Why Don't FP4 Tensor Cores Make Attention Faster? Blackwell FlashAttention-4, Solved with Direct-P and Quantized Backprop TL;DR — Blackwell's FP4 tensor cores handle…

NVIDIA Nemotron 3: Pushing the "Accuracy/Throughput" Frontier with a Hybrid Mamba–Transformer MoE Nemotron 3 combines an MoE hybrid Mamba–Transformer, LatentMoE, MTP,…
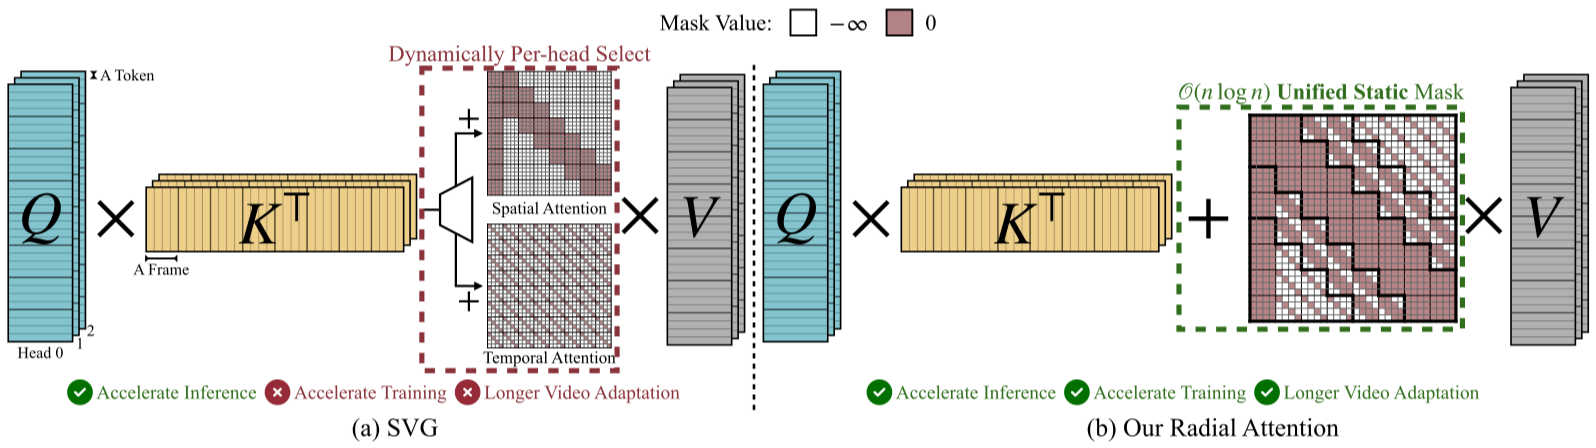
Radial Attention: O(n log n) Sparse Attention with Energy Decay — Generating "Long Videos" Cheaply One-Line Summary (TL;DR) Based on the observation that post-softmax…

NVFP4 4-bit Pretraining, Made Practical: 12B up to 10T Tokens, Effectively On Par with FP8 TL;DR Pretraining a 12B hybrid Mamba-Transformer on 10T tokens at NVFP4 (4-bit)…

Dynamic Memory Sparsification (DMS): Making LLM Hyper-Scaling a Reality with 8× KV Cache Compression One-Line Summary (TL;DR) DMS, combining a lightweight re-fitting of…