FlashMask-3: Efficient and Expressive Mask-Aware Distributed Attention
An analysis of FlashMask-3’s Hopper kernels, mask localization, load balancing, communication overlap, and long-context training results and limitations.
An analysis of FlashMask-3’s Hopper kernels, mask localization, load balancing, communication overlap, and long-context training results and limitations.
Flash-dLLM: I/O-First Diffusion LLM Acceleration, Unlocking 210.6 tokens/s with Fused Cache and Self-Verification One-Line Summary (TL;DR) Diffusion LLMs (dLLMs) support…
VC-Attention is a training-free kernel that removes value-quantization and softmax bottlenecks in low-bit video-DiT attention, speeding it up 1.59× on B200.
Why Don't FP4 Tensor Cores Make Attention Faster? Blackwell FlashAttention-4, Solved with Direct-P and Quantized Backprop TL;DR — Blackwell's FP4 tensor cores handle…

Structured State Space Duality: Unifying SSMs and Attention with Mamba-2 for 2–8× Acceleration TL;DR Structured State-Space Duality (SSD) reveals that SSMs and masked…

Hydragen: The Secret Weapon for Decoding Large Batches with Shared Prefixes up to 32× Faster TL;DR By decomposing the prefix and suffix using softmax denominator…
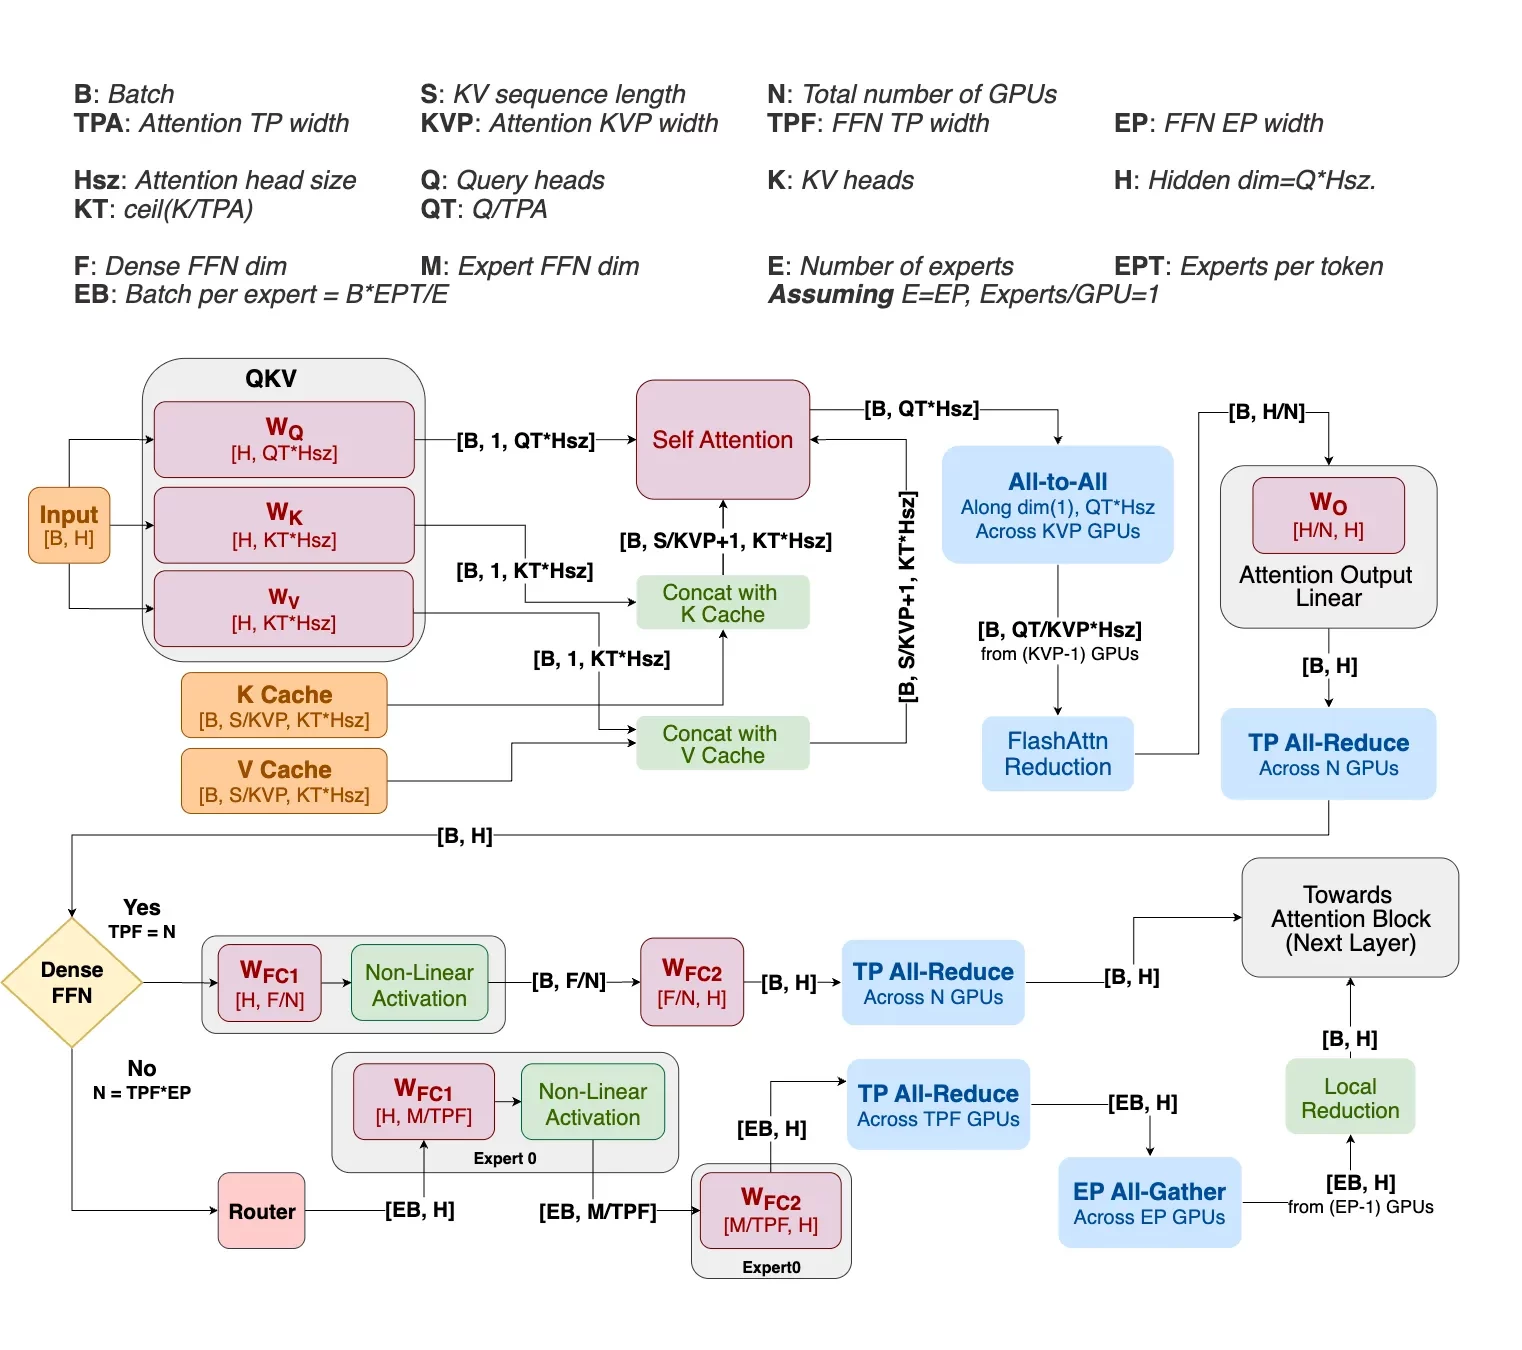
Helix Parallelism: Breaking the Latency-Throughput Wall of Ultra-Long LLM Decoding TL;DR Helix Parallelism schedules Attention and FFN with different parallelism…
Native Sparse Attention (NSA) — 11× faster even at 64k tokens, accuracy intact One-line summary (TL;DR) NSA combines a three-branch sparse attention — “compress → select…