Separate inference from training
SageAttention3 targets FP4 inference; SageBwd targets INT8 training. Of seven forward/backward matmuls, $dOV^\top$ stays FP16. (§3–4)
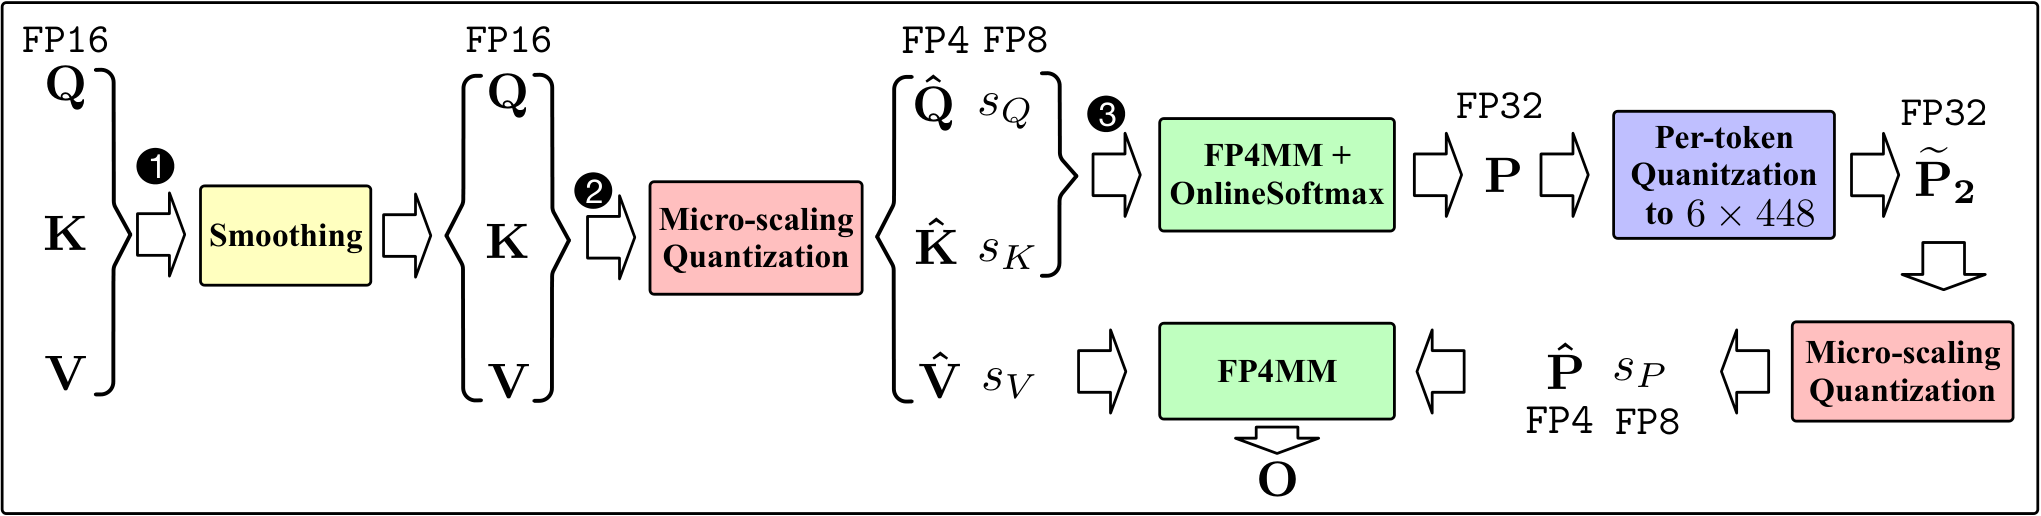
Zhang et al., Figure 2. Original , CC BY 4.0 , unchanged.
The FP16-input → in-kernel quantization workflow does not establish persistent FP4 KV-cache storage. (Algorithm 1)
Worked example: FP4 is not integer INT4
NVIDIA’s format documentation specifies a maximum E2M1 magnitude of 6. NVFP4 shares an FP8 scale across 16 values and also uses a global FP32 scale. This format description is separate from SageAttention3’s full two-level softmax scaling procedure.
The following is an independently constructed numerical example. Fix the global scale at 1. Form a 16-value block from [0, 0.7, 1.4, 3] followed by twelve zeros. The maximum magnitude is 3, so the block scale is $s=3/6=0.5$, exactly representable in FP8 E4M3.
| Stage | First four values |
|---|---|
| Input | 0, 0.7, 1.4, 3 |
| Divide by $s$ | 0, 1.4, 2.8, 6 |
| Nearest E2M1 values | 0, 1.5, 3, 6 |
| Multiply by $s$ | 0, 0.75, 1.5, 3 |
The remaining twelve zeros are unchanged. Maximum absolute error is 0.1; mean squared error over all sixteen values is 0.00078125. The code value 1.5 also illustrates why this is not integer INT4 rounding. This example demonstrates quantization error; it does not measure attention outputs or model quality.
Compute precision does not establish storage savings
For an independent storage calculation, assume packed bits without padding and count just one FP8 block scale:
| Assumption | Bytes |
|---|---|
| Sixteen FP16 values | 32 |
| Sixteen FP4 values plus one 8-bit scale | 9 |
The reduction is $1-9/32=71.875\%$, excluding the global scale, alignment and other metadata. A 75% reduction in payload bits alone does not prove the same reduction in actual storage or total VRAM. A KV-cache claim requires checking the cache’s persistent dtype and metadata separately.
Kernel speed and complete workloads
| Scope | Reported result |
|---|---|
| Inference kernel, RTX5090 | 1038 TOPS, about 5× versus FlashAttention2 |
| Forward/backward kernel, RTX4090 | Up to 1.67× versus FlashAttention2 |
| HunyuanVideo (versus Original) | 489 s → 164 s |
| Llama 16K iteration (versus Original) | 6.0 s → 5.2 s |
Sources: §5.2, Table 4.
Illustrative timing calculation: suppose attention takes 40 ms of a 100 ms workload, leaving 60 ms elsewhere. A 5× attention speedup gives $60+40/5=68$ ms overall, or about 1.47×. Additional quantization overhead would change this estimate. These are invented timing assumptions, not a reproduction of the paper’s benchmarks.
Limitations and application judgment
Pretraining converged more slowly. (§5.2) Reviewer judgment: fine-tuning results do not guarantee lossless training everywhere. Measure kernel time, complete-workload time, quality and storage separately. The former unconditional quality and KV-memory claims have been removed.
Comments