![[Paper Review] Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models](https://paper-assets.alphaxiv.org/figures/2601.07372v1/img-0.jpeg)
[Paper Review] Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
Paper Engram: The Second Sparsity Axis After Conditional Computation (MoE), Conditional MemoryOne-Line Summary (TL;DR)Engram adds a …
All posts on technology, daily life, and thoughts.
![[Paper Review] Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models](https://paper-assets.alphaxiv.org/figures/2601.07372v1/img-0.jpeg)
Paper Engram: The Second Sparsity Axis After Conditional Computation (MoE), Conditional MemoryOne-Line Summary (TL;DR)Engram adds a …
![[Paper Review] Continuous Autoregressive Language Models](https://discuss.pytorch.kr/uploads/default/original/2X/d/d1107e24375fae20a5f3a4733826880ce5d817db.png)
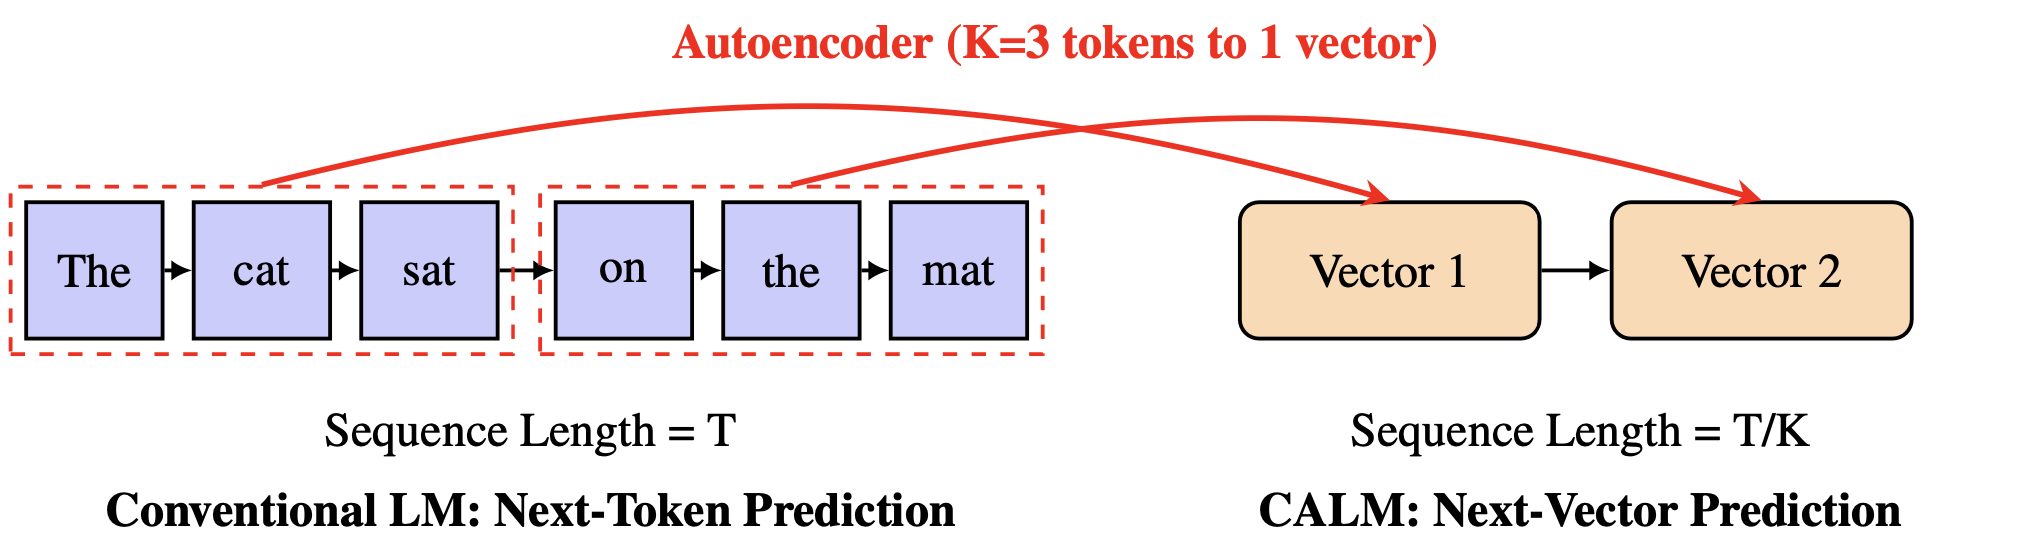
Paper CALM: Bypassing the Token-by-Token Bottleneck with “Continuous Vector-by-Vector” Likelihood-Free Language ModelingCALM …
![[Paper Review] Memory Retrieval and Consolidation in Large Language Models through Function Tokens](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/memory-retrieval-and-consolidation-in-large-language-models-through-function-tokens-4.png)
Paper Function Token Hypothesis: Why Punctuation and Newlines Gate LLM “Memory Retrieval”One-line Summary (TL;DR)This paper …
![[Paper Review] NVIDIA Nemotron 3: Efficient and Open Intelligence](https://developer-blogs.nvidia.com/wp-content/uploads/2025/12/image3-8-png.webp)
Paper NVIDIA Nemotron 3: Pushing the “Accuracy/Throughput” Frontier with a Hybrid Mamba–Transformer MoENemotron 3 combines an …
![[Paper Review] Radial Attention: O(n log n) Sparse Attention with Energy Decay for Long Video Generation](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/radial-attention-onlog-n-sparse-attention-with-energy-decay-for-long-video-generation-2.png)
Paper Radial Attention: O(n log n) Sparse Attention with Energy Decay — Generating “Long Videos” CheaplyOne-Line Summary …
![[Paper Review] Attention Sinks and Compression Valleys in LLMs are Two Sides of the Same Coin](https://cdn-uploads.huggingface.co/production/uploads/6317233cc92fd6fee317e030/yNP71PjobVvLDgJ0R0qV2.png)
Paper One Narrative Forged by Massive Activations: Bridging Attention Sink and Compression ValleyTL;DRMassive activations in the residual …