SMELT: Scaling Laws for Compute-Matched MoE Looped Transformers
SMELT: Scaling Laws for Compute-Matched MoE Loop Transformers TL;DR Loop transformers scale depth by executing a layer block repeatedly, but most prior work fixed only…
All posts on technology, daily life, and thoughts.
SMELT: Scaling Laws for Compute-Matched MoE Loop Transformers TL;DR Loop transformers scale depth by executing a layer block repeatedly, but most prior work fixed only…
The Recurrent Half Is the Easy-to-Quantize Half: Why Gated DeltaNet Survives at 4 Bits TL;DR — The 48 recurrent Gated DeltaNet (GDN) layers of a hybrid 27B LLM…
The Scores Were a Waste: The Paradox Where 'Random Sampling' Ties the Strongest in KV Cache Eviction — An In-Depth Review of Random Attention TL;DR — Research on…

Engram: The Second Sparsity Axis After Conditional Computation (MoE), Conditional Memory One-Line Summary (TL;DR) Engram adds a "knowledge lookup primitive" to the…
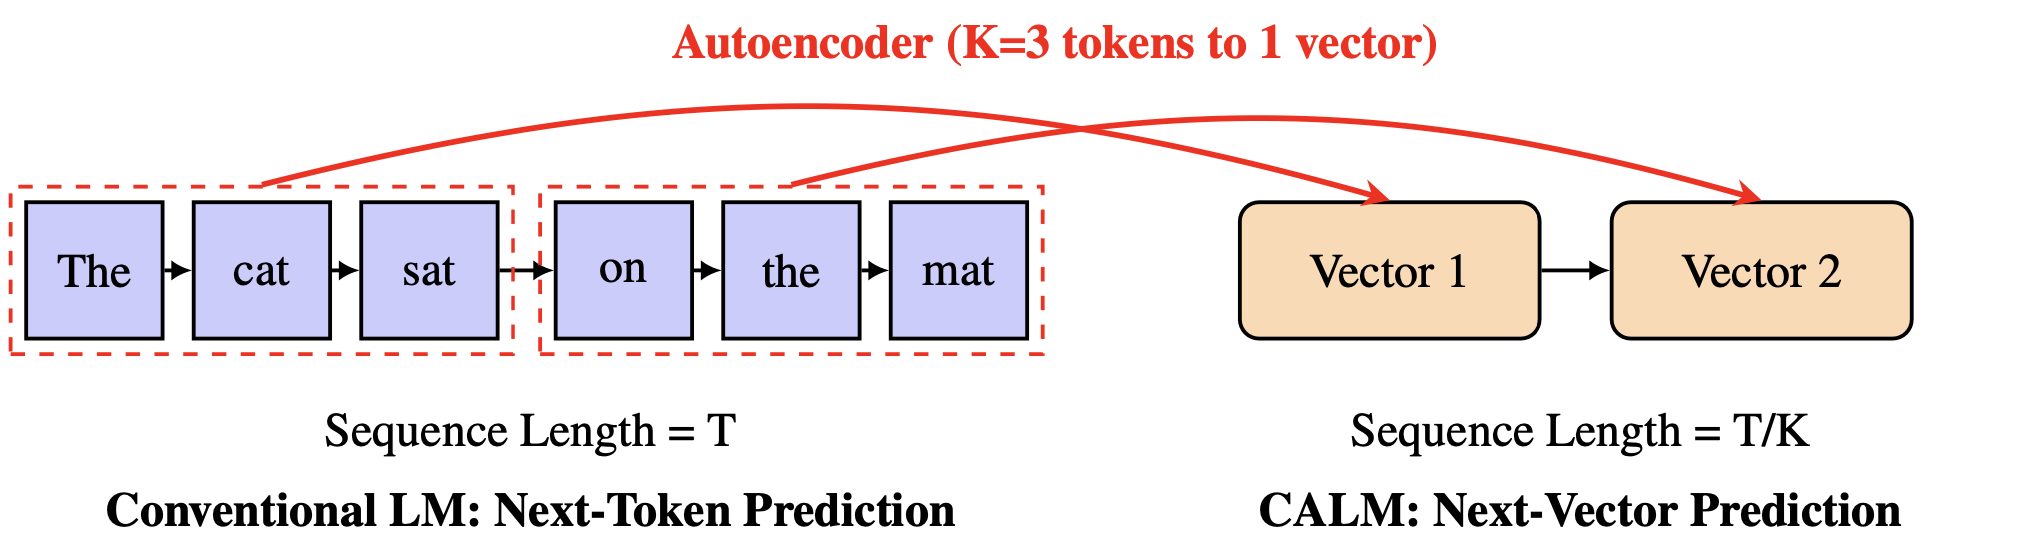
CALM: Bypassing the Token-by-Token Bottleneck with "Continuous Vector-by-Vector" Likelihood-Free Language Modeling CALM (Continuous Autoregressive Language Models)…

Function Token Hypothesis: Why Punctuation and Newlines Gate LLM "Memory Retrieval" One-line Summary (TL;DR) This paper defines LLM memory as "reactivation of features…