![[Paper Review] Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models](https://paper-assets.alphaxiv.org/figures/2601.07372v1/img-0.jpeg)
[Paper Review] Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
Engram: The Second Sparsity Axis After Conditional Computation (MoE), Conditional Memory One-Line Summary (TL;DR) Engram adds a "knowledge lookup primitive" to the…
![[Paper Review] Attention Sinks and Compression Valleys in LLMs are Two Sides of the Same Coin](https://cdn-uploads.huggingface.co/production/uploads/6317233cc92fd6fee317e030/yNP71PjobVvLDgJ0R0qV2.png)
![[Paper Review] Hardware-Efficient Attention for Fast Decoding](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/hardware-efficient-attention-for-fast-decoding-1.png)
![[Paper Review] Marconi: Prefix Caching for the Era of Hybrid LLMs](https://pbs.twimg.com/media/GdyLXO9W4AADox0.jpg)
![[Paper Review] SGLang: Efficient Execution of Structured Language Model Programs](https://cdn.bytez.com/mobilePapers/v2/neurips/94872/images/20-0.png)
![[Paper Review] Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality](https://icml.cc/media/PosterPDFs/ICML%202024/32613.png)
![[Paper Review] KIMI K2: OPEN AGENTIC INTELLIGENCE](https://github.com/MoonshotAI/Kimi-K2/raw/main/figures/kimi-logo.png)
![[Paper Review] Qwen 3 Technical Report](https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/logo_qwen3.png)
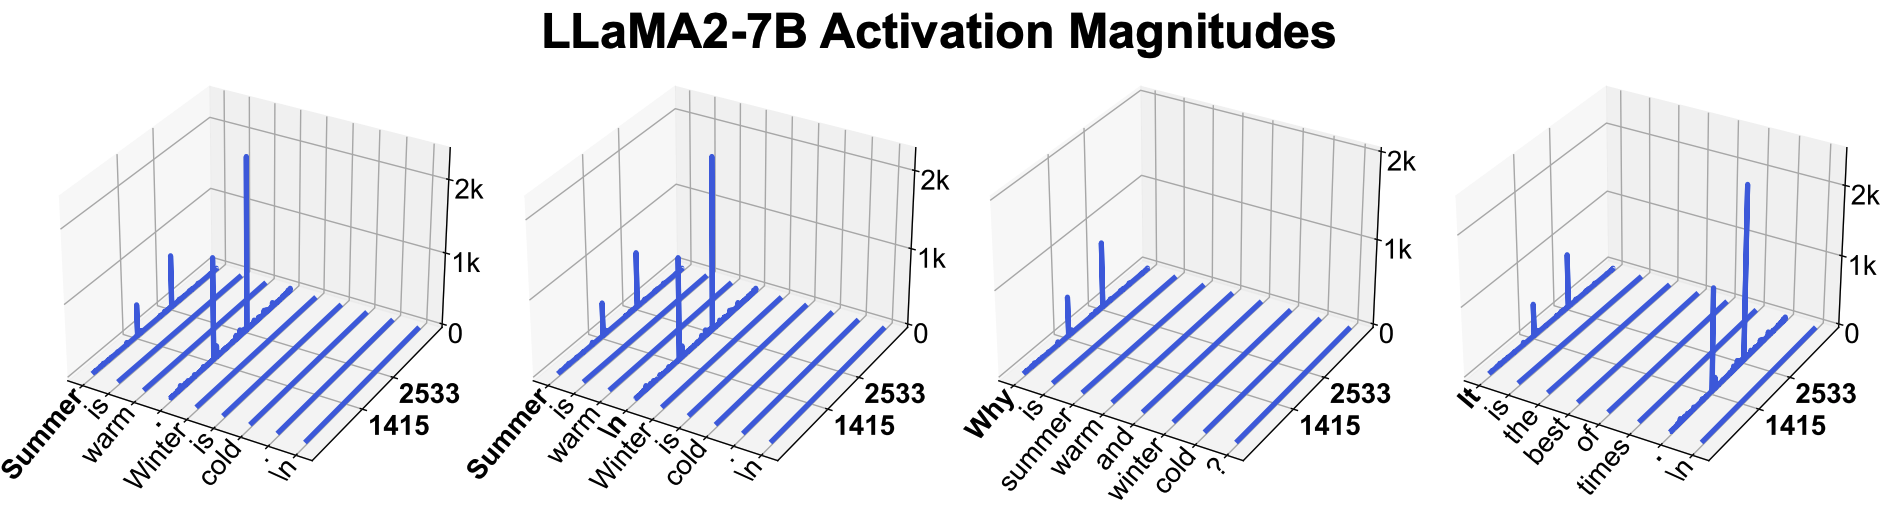
![[Paper Review] Massive Activations in Large Language Models](https://eric-mingjie.github.io/massive-activations/assets/main_teaser_final.png)
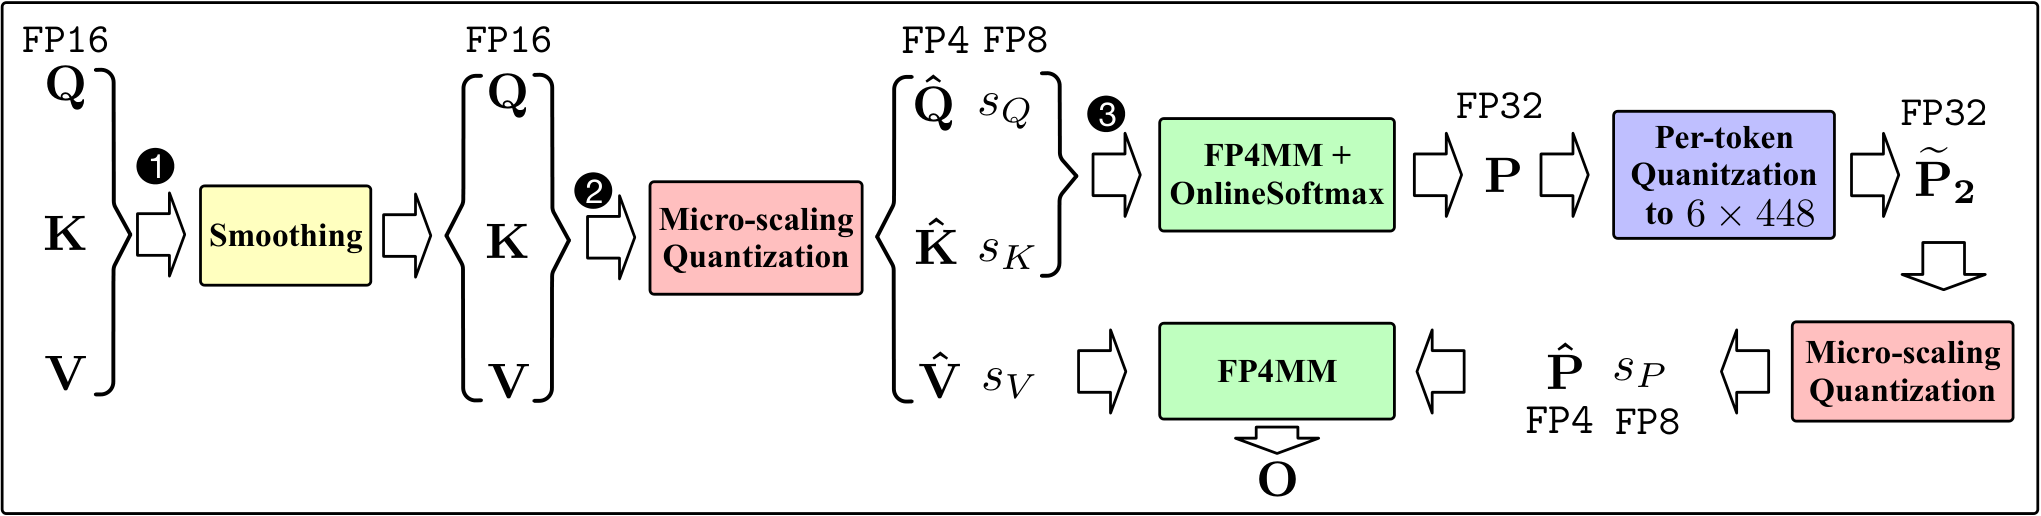
![[paper review] SageAttention3: Microscaling FP4 Attention for Inference and An Exploration of 8-bit Training](/assets/images/papers/2505.11594/figure-2.png)
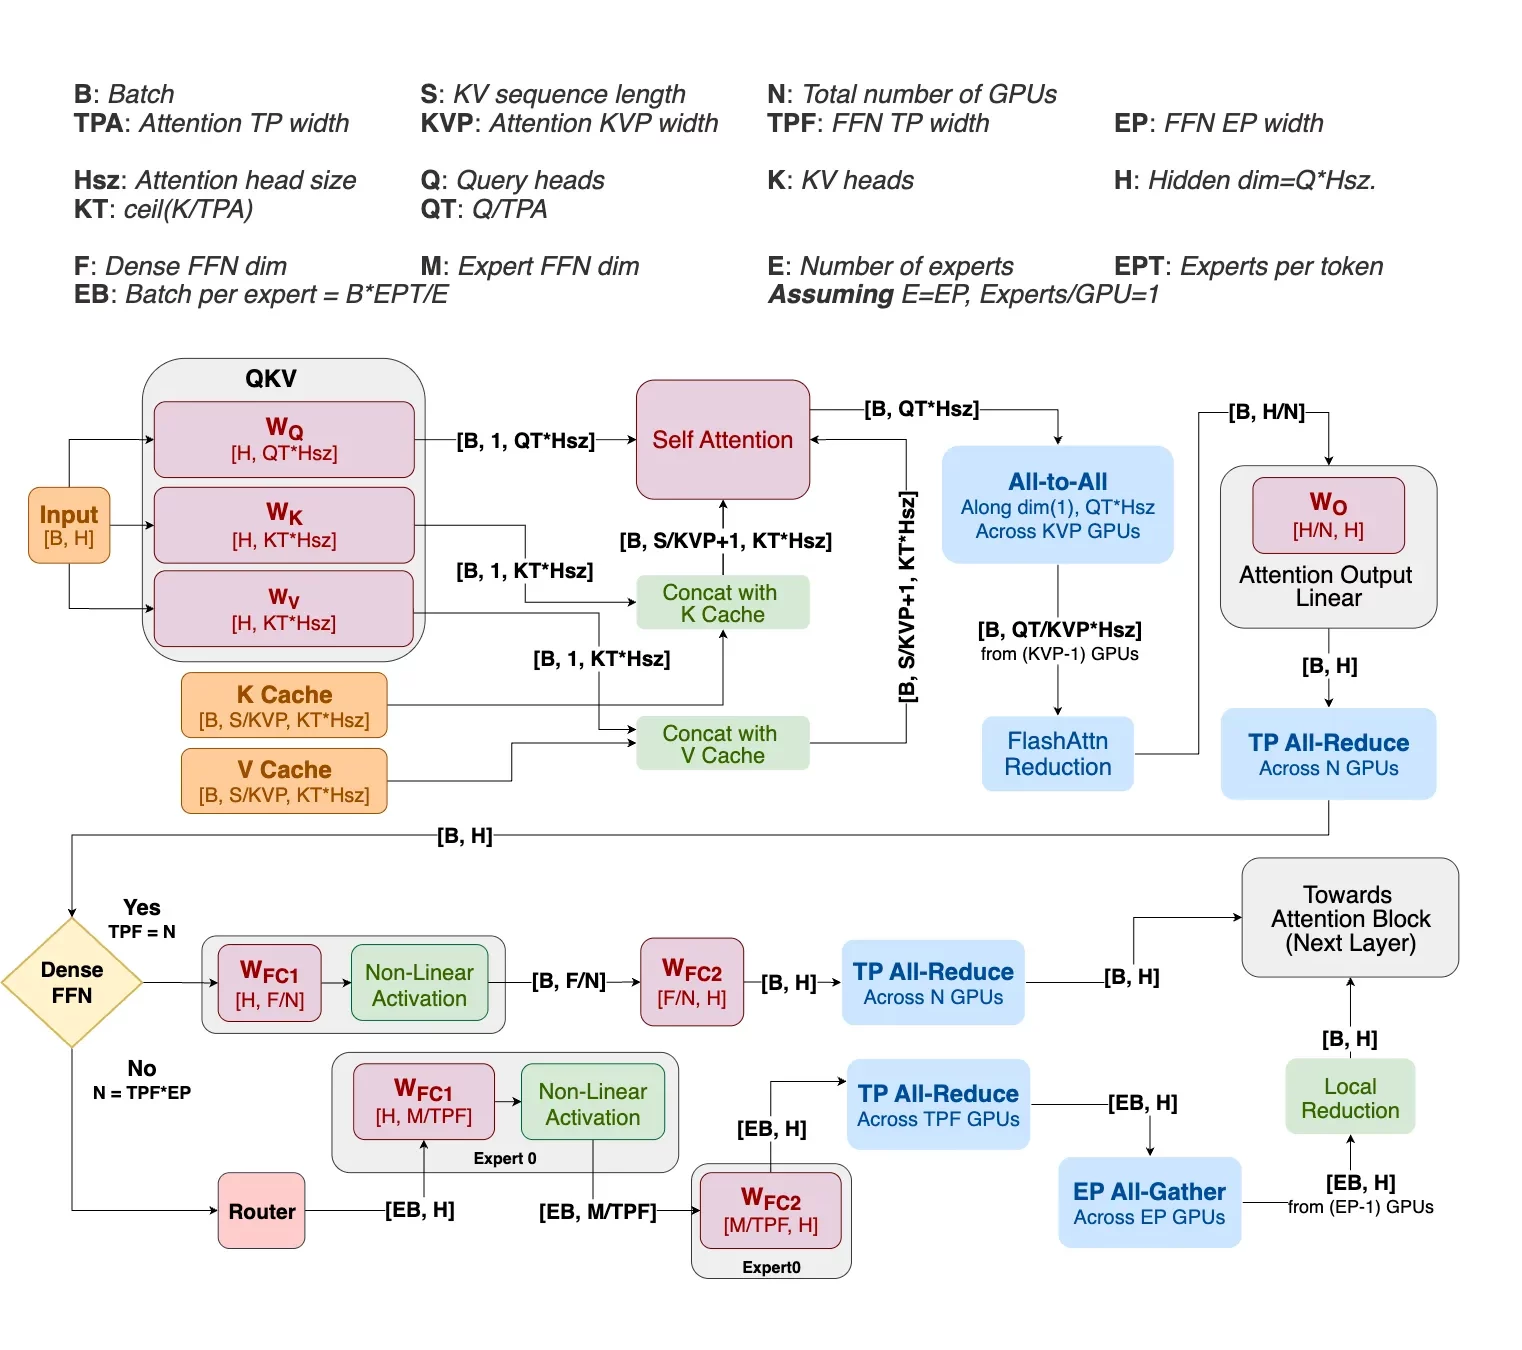
![[Paper Review] Helix Parallelism: Rethinking Sharding Strategies for Interactive Multi-Million-Token LLM Decoding](https://www.storagereview.com/wp-content/uploads/2025/07/image2-2-png-e1752234784623.webp)