TAO: Tool-Aware Joint Scheduling for LLM-Based Agentic Serving
TAO: Tool-Aware Joint Scheduling for LLM-Based Agentic Serving Original: Shuhuai Li et al., "TAO: Tool-Aware Joint Scheduling for LLM-Based Agentic Serving"…
TAO: Tool-Aware Joint Scheduling for LLM-Based Agentic Serving Original: Shuhuai Li et al., "TAO: Tool-Aware Joint Scheduling for LLM-Based Agentic Serving"…
The problem: re-reading the image at every step Diffusion language models that answer questions from images do not complete a response in one pass. While filling in the…
Diffusion language models must decide 'what' and 'where' at the same time Diffusion language models generate sentences by repeatedly filling masked tokens. To decode…
Introduction In settings where the batch size is close to 1, such as conversational services, the latency of a mixture-of-experts language model comes mostly from reading…
Recent language models keep increasing the amount of information packed into a single vocabulary entry. Per-layer embeddings (PLE), first introduced in Gemma 3n, carried…
Problem: Why It's Hard to Unify Understanding and Generation in One Representation There have been many attempts to merge image understanding and image generation into a…
Introduction A game world built by a video generation model alone stores off-screen state nowhere. Every time a corridor you have already passed through is redrawn, it…
Introduction In models that handle long contexts, the compression operation that reduces multiple tokens to a single vector becomes a performance bottleneck. This paper…
The sequential bottleneck of sampling one token at a time Large language models can compute an entire sentence in parallel during training, but when generating text they…
The Cost and Accuracy Dilemma of Long Agent Trajectories LLM agents accumulate long trajectories by repeating reasoning and tool calls for hundreds of rounds. To make…
Speculative sampling reuses future video predictions to reduce response latency. How it works, recomputation costs, and the limits of the serving experiments.
MemT-1.0 stores conversation history in a fixed-size matrix state. We examine memory updates, information loss, and how the approach compares with full-context and…
DLite explained through a candidate-verification example, cache ownership, and a careful comparison of acceptance length and decoding speed.
An analysis of FlashMask-3’s Hopper kernels, mask localization, load balancing, communication overlap, and long-context training results and limitations.
An analysis of SpecAgent, where a weaker model drafts tool calls and a stronger model verifies them, covering its design, experimental results, and limitations.
HLA-WM retrieves past chunks using camera geometry to restore scene memory. At 60 seconds, its history memory is about 12× smaller than Full KV and 6× larger than GDN,…
DCOCO reselects existing parallel draft candidates using contextual scores. This review distinguishes accepted length from actual throughput and examines correction…
Fixed-point behavior connects KV sharing, state reuse, and distilled prefill in looped language models. We review the savings and accuracy trade-offs demonstrated on…
SparseDecoding calibrates pruning on model-generated tokens and adds a decoding-specific sparse kernel. We examine the conditions behind its maximum 1.48× speedup on A100…
MC-Sparse separates three sources of quality and efficiency loss in sparse DiT attention. This review explains why token selection and kernel execution costs must be…
TokenRouter: An Efficient Serving System for Token-Level LLM Routing TL;DR — Routing an LLM at the token level rather than the session/query level can substantially push…
Mechanics of Long-Context Hybrid Models: From Hybrid Attention to Hybrid Position TL;DR — These days open-source LLMs are rapidly shifting from models that "use full…
TRACE: Rollout-Aligned FP4 Quantization-Aware Training — MoE LLM RL at BF16 Quality, up to 5.4x Faster TL;DR In reinforcement learning (RL) for MoE LLMs, quantizing…
SlimKV: Compressing Tokens and Features Together, Cutting the KV Cache by up to 32× with Reconstruction-Free Latent-Space Attention TL;DR SlimKV is a question-agnostic…
TaSQ: 'Tailored Design' of the Quantization Space for a 1-bit KV Cache TL;DR — TaSQ (Tailored Space Vector Quantization) redesigns the very target space to which vector…
How to Hand Off KV Caches As-Is Between Different LLMs: HeteroFold TL;DR: HeteroFold, a method that reuses the KV cache between models with different tokenizers and…
On-Policy Is Not a Panacea: The Real Protagonists of Rollout Policy, KL Direction, and Learning Rate in Distillation Dynamics TL;DR — When we separate on-policy (OnPD)…
The KV Cache Is the New Memory Wall: Three Regimes and Five Domains of Long-Context LLM Inference TL;DR — Long-context LLM decode inference is bound by memory bandwidth,…
WavePP — A Pipeline-Parallel Prefill Runtime That Burns In Prefix Reuse TL;DR Built on top of TensorRT-LLM, WavePP overlaps request admission (reuse consensus, cache…
Phase Sensitivity: The 'Periodic Weakness' Created by Chunked KV-Cache Compression TL;DR — In models that use chunked KV-cache compression (such as the DeepSeek-V4…
Paper MassAlloc Attention (MALA): Letting Attention Allocate Its Own Compute TL;DR — Full softmax attention (FullAttn) performs all post-score computation after QK score…
WorldAttention: System Co-Design of an Interactive Video World Model That Drops the Sliding Window TL;DR — Text-controlled interactive video world models are trapped…
PISA: Pyramid Top-$K$ Selection Lowers the Cost of Block-Sparse Attention to $O(N\log N)$ TL;DR — Block-sparse attention makes attention computation linear, but block…
Who pays for the KV cache? — Kubernetes, gateway, and provider bills in one ledger TL;DR — The cost of a single AI feature is scattered across three disconnected ledgers:…
LumoTree: Path-Parallel Speculative Verification for Hybrid Language Models TL;DR — Tree speculative decoding in hybrid models that mix Gated DeltaNet with full attention…
SPECTRA: A Reconfigurable LLM Accelerator That Changes Its Hardware With Every Inference Stage TL;DR Speculative decoding oscillates between prefill (compute-bound GEMM),…
Branching on Compressed Memory: Adding Tree Reasoning to DeepSeek-V4 TL;DR Adding tree-structured speculative decoding to DeepSeek-V4-Flash yields longer acceptance…
Flash-dLLM: I/O-First Diffusion LLM Acceleration, Unlocking 210.6 tokens/s with Fused Cache and Self-Verification One-Line Summary (TL;DR) Diffusion LLMs (dLLMs) support…
Parallel Inference without Drafter-Side KV Cache: H-Spec's Hybrid Speculative Decoding TL;DR shows that the bottleneck in concurrent serving is that a block-diffusion…
Analytical PD-inference provisioning uses instance counts and KV-cache reservations to find the lowest-power deployment for a target capacity.
VC-Attention is a training-free kernel that removes value-quantization and softmax bottlenecks in low-bit video-DiT attention, speeding it up 1.59× on B200.
ActionPiece: Rethinking Action Tokenization Beyond Reconstruction Error, via Physical Ranking TL;DR — In autoregressive VLA (vision-language-action) models, the action…
DeepSeek-V4.1-Flash: A Multimodal MoE That Cuts the KV Cache to 1/4 While Raising Performance Further TL;DR. DeepSeek-V4.1-Flash, released by DeepSeek-AI, is a multimodal…
Fathom: Accelerating 1M-Token Decoding by 1.67x with Query-Adaptive Depth Scanning TL;DR When agent sessions stretch to 1M tokens and dozens of sessions reside…
Waking the MoE on SSD: Serving a 35B MoE at 20 tok/s on a 24 GB Desktop with Edge0 One-line summary (TL;DR) Even at 4-bit, a 35B-class MoE occupies 19.5 GB and cannot…
StepAudio 3 Gen: Unifying Speech, Song, Music, and Sound Effects with a Single Discrete Autoregressive (RVQ) Model TL;DR StepAudio 3 Gen, released by StepFun, is a fully…
Is "Lossless" Speculative Decoding Really Lossless? — The Numerical-Precision Trap Exposed by Reproducing Orthrus TL;DR — Orthrus attaches a diffusion view to a frozen AR…
ZGCM-1: How a 7B Dense Model Trades Blows with 235B Frontiers — A Fully Open, Ultra-Efficient Foundation Model Design Report TL;DR — With a single 7.39B dense model,…
Programmable World Model — Embedding "Executable State" into Generative Worlds One-Line Summary (TL;DR) Video world models are producing increasingly realistic…
SAS: A Simple Attention Sparsification That Learns Context Ranking Directly Without Distillation TL;DR — In post-training attention sparsification, inject the continuous…
CoVeR: Coverage-Based Pruning That Cuts Visual Tokens of Multi-View 3D Reasoning by up to 92% Using Geometry Alone One-Line Summary (TL;DR) Rendering a 3D scene into…
Marigold V2: Reviving an Image-Editing Diffusion Transformer (DiT) as a Monocular Depth Estimator TL;DR This study fine-tunes an image-editing diffusion transformer…
SQS: Fusing Pruning and Quantization into One Bayesian Learning — Where Spike-and-Slab Meets GMM TL;DR — Doing pruning and low-bit quantization separately leaves…
Linear Attention Rewritten with a Kalman Filter: Kalman Delta Networks TL;DR The fixed-size recurrent memory update of linear attention is reinterpreted as a…
X-AuT: Pruning Audio Encoders in Speech LLMs with Behavioral Probes and Cross-Scale Distillation TL;DR X-AuT is a framework that progressively prunes the audio encoder…
Deadline-Filling Prefill Chunks: SLOWeave — An Adaptive Chunking Scheduler for LLM Serving TL;DR — Instead of a fixed prefill chunk size, we propose SLOWeave, an online…
Why Are Video LLMs Still So Expensive? — A Four-Stage Guide to Inference Efficiency Mechanisms TL;DR — This paper classifies 125 VideoLLM inference efficiency studies…
Miles v0.1: A "verified, clean, and scalable" full-stack system for frontier RL post-training TL;DR: Miles is a full-stack RL post-training framework that resolves the…
Two Designs That Make Speculative Decoding Practical for Large-Scale, Long-Context RL Post-Training TL;DR : Rollout generation dominates the wall-clock time of RL…
Cache-Learning Routers: Cache-Aware Joint Router Adaptation for Memory-Constrained MoE Inference TL;DR Starting from the observation that MoE's real bottleneck is not…
VestigeKV: The Degenerate RoPE Branch Carries Its Own Cache Eviction Signal TL;DR In NoPE-MLA models (Kimi Linear 48B), reading only 11% of each row — the 64-dim…
ShallowStream: Index Shallowly, Answer Deeply — Unlocking the Computational Bottleneck of Streaming Video Understanding TL;DR — In streaming video understanding, the most…
Uno: AR and Diffusion in One Model — Lossless Parallel Generation for LLM Acceleration TL;DR — LLMs are slow because next-token prediction (NTP) can emit only one token…
Catch the Moment a Model "Revisits Its Thoughts": How BeaconKV Compresses Reasoning KV Caches 5.8× with Beacon Queries TL;DR — The KV cache of a Large Reasoning Model…
Why Don't FP4 Tensor Cores Make Attention Faster? Blackwell FlashAttention-4, Solved with Direct-P and Quantized Backprop TL;DR — Blackwell's FP4 tensor cores handle…
Language Models Control Their Own Attention: Declarative Attention TL;DR — Existing sparse attention methods still paid $O(N)$ per decoding step by approximating…
Same Request, Different Answer: Prefix Caching Makes Serving Non-Reproducible, and Quantization Amplifies It TL;DR — Prefix caching is billed as a "transparent…
SGD-KV: Finding 'heads that are good at summarizing' cuts the 1M-token KV cache by up to 75% TL;DR — Attention heads do not all do the same job. SGD-KV pinpoints the…
SMELT: Scaling Laws for Compute-Matched MoE Loop Transformers TL;DR Loop transformers scale depth by executing a layer block repeatedly, but most prior work fixed only…
The Recurrent Half Is the Easy-to-Quantize Half: Why Gated DeltaNet Survives at 4 Bits TL;DR — The 48 recurrent Gated DeltaNet (GDN) layers of a hybrid 27B LLM…
The Scores Were a Waste: The Paradox Where 'Random Sampling' Ties the Strongest in KV Cache Eviction — An In-Depth Review of Random Attention TL;DR — Research on…

Engram: The Second Sparsity Axis After Conditional Computation (MoE), Conditional Memory One-Line Summary (TL;DR) Engram adds a "knowledge lookup primitive" to the…
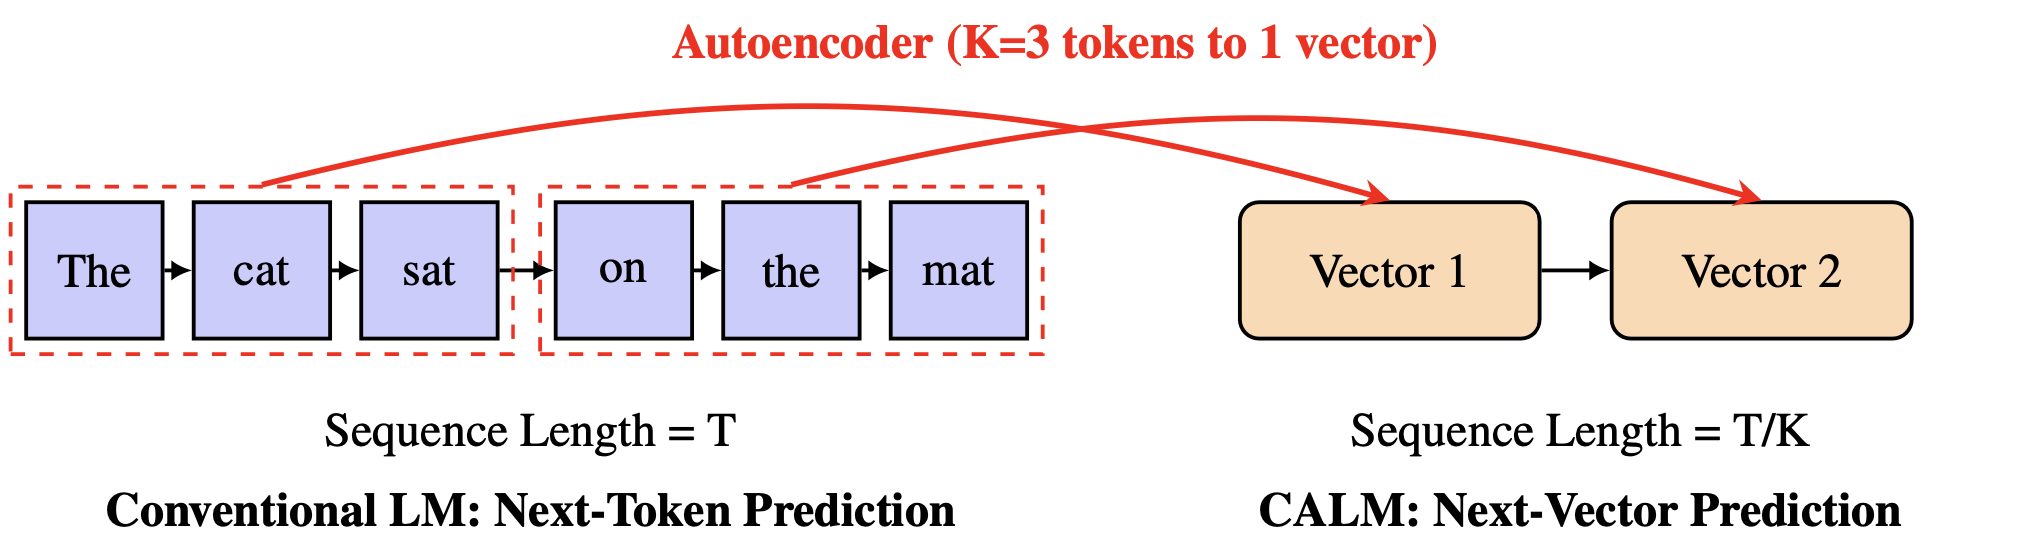
CALM: Bypassing the Token-by-Token Bottleneck with "Continuous Vector-by-Vector" Likelihood-Free Language Modeling CALM (Continuous Autoregressive Language Models)…

Function Token Hypothesis: Why Punctuation and Newlines Gate LLM "Memory Retrieval" One-line Summary (TL;DR) This paper defines LLM memory as "reactivation of features…

NVIDIA Nemotron 3: Pushing the "Accuracy/Throughput" Frontier with a Hybrid Mamba–Transformer MoE Nemotron 3 combines an MoE hybrid Mamba–Transformer, LatentMoE, MTP,…

Radial Attention: O(n log n) Sparse Attention with Energy Decay — Generating "Long Videos" Cheaply One-Line Summary (TL;DR) Based on the observation that post-softmax…

One Narrative Forged by Massive Activations: Bridging Attention Sink and Compression Valley TL;DR Massive activations in the residual stream (especially BOS) form a…

GTA & GLA: Hardware-Efficient Attention That Breaks the 'Memory-Dominated' Decode TL;DR GTA (key–value tying) and GLA (latent head sharding) raise FLOPs/byte and shrink…
"Let's put an OS on the GPU": A proposal for a GPU multitasking OS layer for the LLM era One-line summary (TL;DR) In LLM serving, GPUs often stay at ≤10% utilization…
DroidSpeak: Reducing Prefill Latency by 1.7–3.1× through Cross-LLM Prefix-KV Reuse TL;DR When multiple LLMs share the same architecture but different weights, DroidSpeak…

Marconi: Rethinking Prefix Caching for the Hybrid LLM Era TL;DR Marconi introduces a prefix-caching framework for hybrid LLM inference (Attention + SSM). It selectively…

SGLang & RadixAttention: How Execution Optimization for "LM Programs" Achieved a 6.4x Speedup TL;DR By combining a language-runtime co-design with RadixAttention (radix…

Structured State Space Duality: Unifying SSMs and Attention with Mamba-2 for 2–8× Acceleration TL;DR Structured State-Space Duality (SSD) reveals that SSMs and masked…

Dynamic Memory Sparsification (DMS): Making LLM Hyper-Scaling a Reality with 8× KV Cache Compression One-Line Summary (TL;DR) DMS, combining a lightweight re-fitting of…

Hydragen: The Secret Weapon for Decoding Large Batches with Shared Prefixes up to 32× Faster TL;DR By decomposing the prefix and suffix using softmax denominator…

Kimi K2: An Open-Source LLM’s Leap Toward Agentic Intelligence TL;DR With a 3-stage pipeline consisting of MuonClip pretraining + large-scale agentic tool-use data +…

Qwen 3: The Evolution of a Giant MoE Language Model with Adjustable Reasoning Depth TL;DR (in one line) Qwen 3 couples a user-controllable Thinking Budget with a…
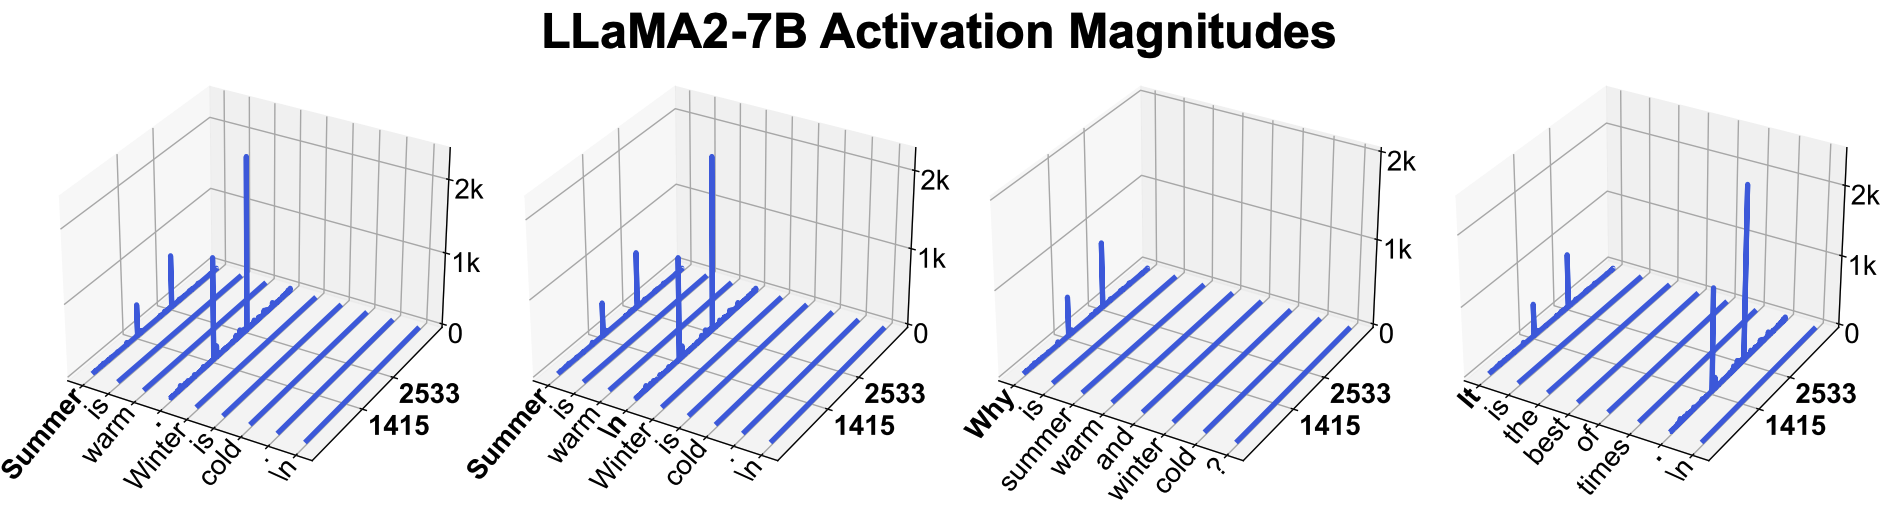
Massive Activations, Hidden Biases: A Reinterpretation of Self-Attention’s Secrets TL;DR Just 4–10 extreme scalar values (×10,000) out of tens of millions can…
Peri-LayerNorm: A Third Option Beyond Post-LN and Pre-LN TL;DR By simply adding another LayerNorm right after the residual connection—"Peri-LayerNorm (Peri-LN)"—the…
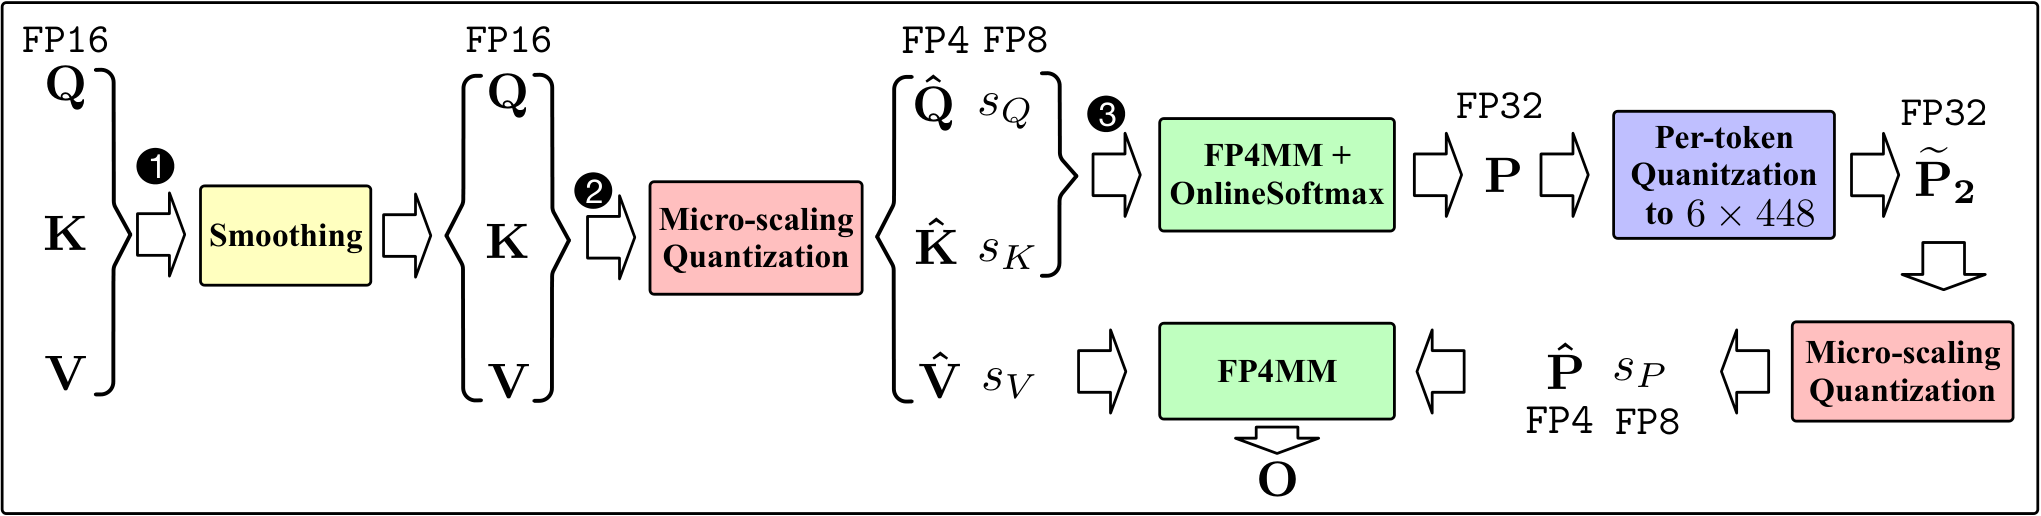
Separate SageAttention3 FP4 inference from SageBwd INT8 training, with checked examples of quantization error, storage overhead and kernel versus whole-workload speed.
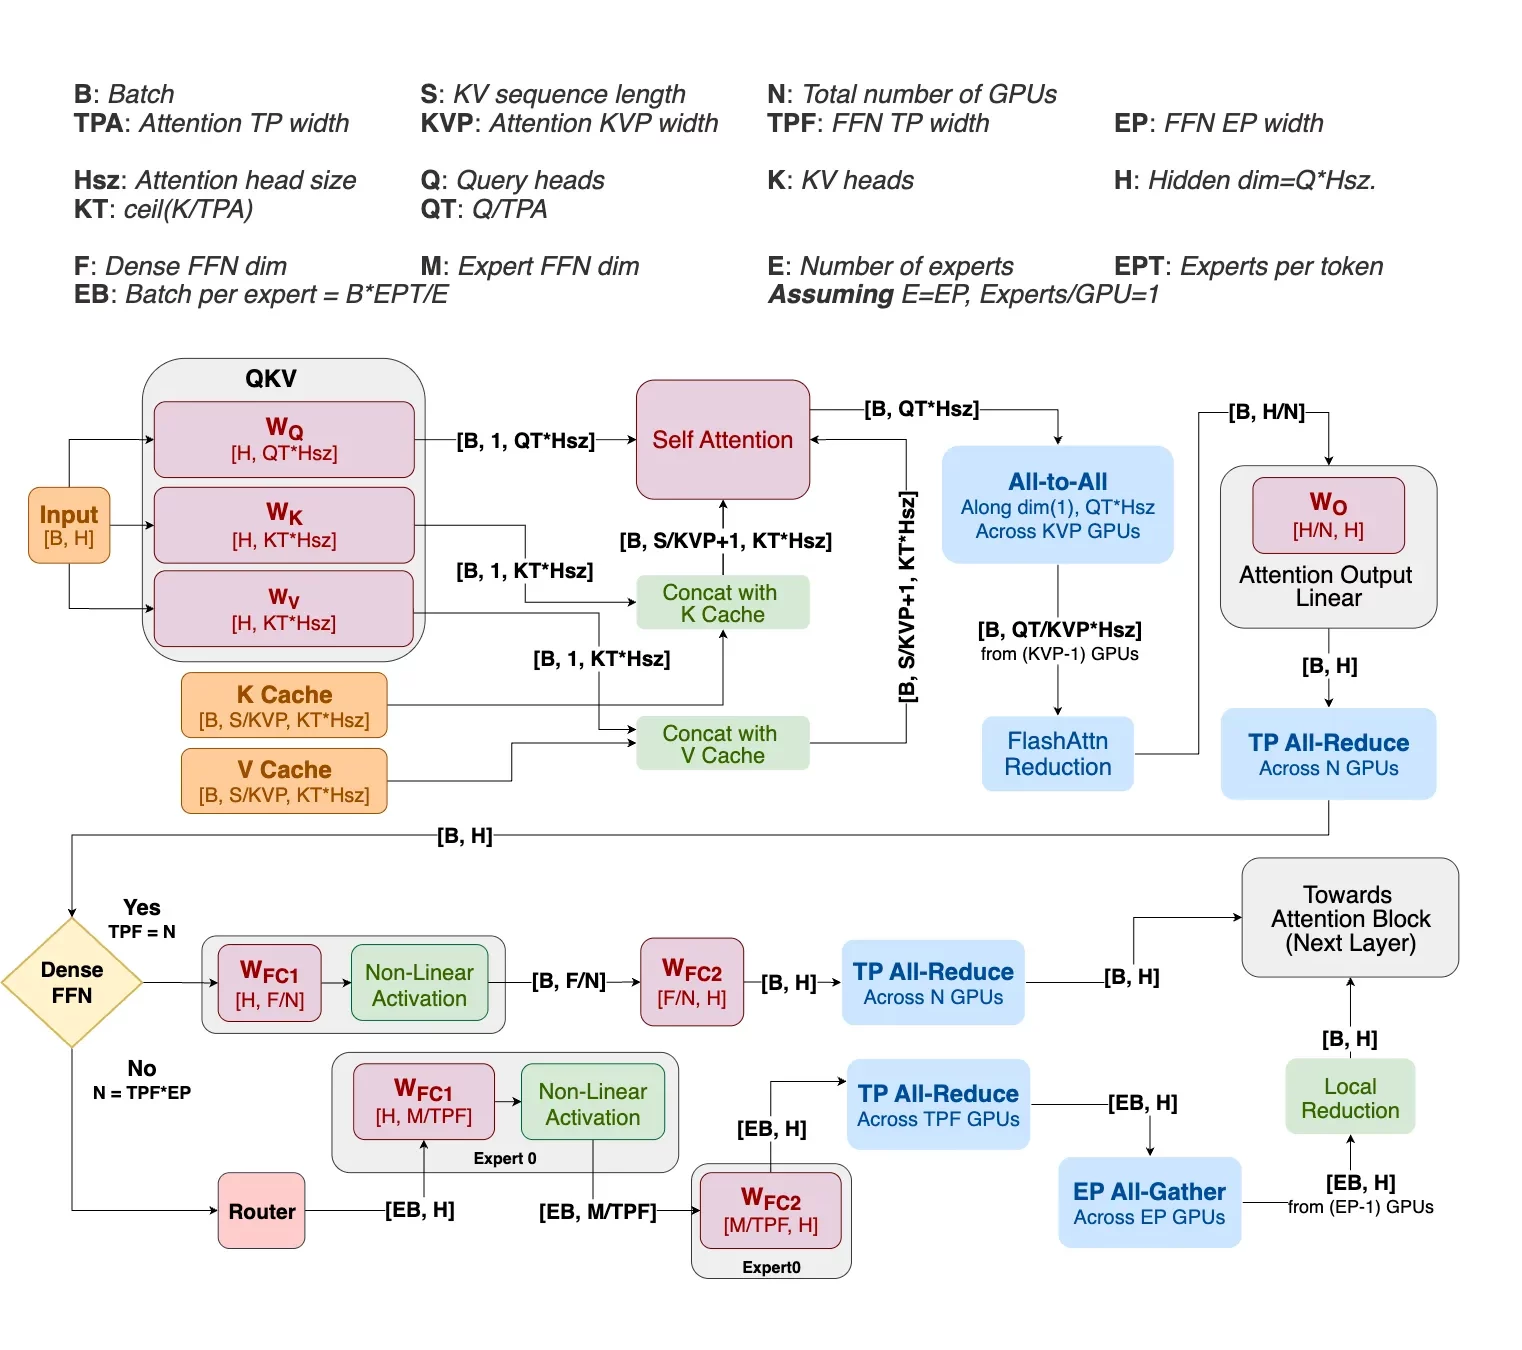
Helix Parallelism: Breaking the Latency-Throughput Wall of Ultra-Long LLM Decoding TL;DR Helix Parallelism schedules Attention and FFN with different parallelism…
Subgoal Curriculum + CoT Consistency: DeepSeek-Prover-V2 Reshapes Automated Theorem Proving TL;DR DeepSeek-Prover-V2, built on the principle of "breaking a problem into…
Inference-Time Scaling: How DeepSeek-GRM Surpassed Giant Models One-Line Summary (TL;DR) "27B model × 32 samples"—With only a Generative Reward Model (GRM) and k-Vote…
CODE I/O: From Code I/O + Natural-Language CoT to General-Purpose Reasoning — Lifting 7B-30B LLMs by +2 Points on Average with Data Design Alone TL;DR A single data…
Native Sparse Attention (NSA) — 11× faster even at 64k tokens, accuracy intact One-line summary (TL;DR) NSA combines a three-branch sparse attention — “compress → select…
Janus-Pro 7B: Dual-Encoder Multimodal LLM That Outsmarts Bigger Models One-line summary (TL;DR) By fully separating the SigLIP understanding encoder from the VQ…
One-line Summary (TL;DR) DeepSeek-V3 is an open-source SOTA that combines Aux-loss-free Load-Balancing Bias, FP8 mixed-precision training, and Multi-Token Prediction in a…
One-line summary (TL;DR) JanusFlow achieves state-of-the-art performance in both image understanding and generation (FID 9.51 / GenEval 0.63 / MMBench 74.9) with a single…