![[논문리뷰]: Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models](https://paper-assets.alphaxiv.org/figures/2601.07372v1/img-0.jpeg)
[논문리뷰]: Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
Engram: 조건부 연산(MoE) 이후의 두 번째 희소성 축, 조건부 메모리(Conditional Memory) 한 줄 요약 (TL;DR) Engram은 Transformer에 “지식 조회(lookup) primitive”를 추가해, 표준 모델이 early layer에서 수행하던 정적 지식/로컬 패턴…
![[논문 리뷰] Attention Sinks and Compression Valleys in LLMs are Two Sides of the Same Coin](https://cdn-uploads.huggingface.co/production/uploads/6317233cc92fd6fee317e030/yNP71PjobVvLDgJ0R0qV2.png)
![[논문 리뷰] Hardware-Efficient Attention for Fast Decoding](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/hardware-efficient-attention-for-fast-decoding-1.png)
![[논문리뷰] Marconi: Prefix Caching for the Era of Hybrid LLMs](https://pbs.twimg.com/media/GdyLXO9W4AADox0.jpg)
![[논문리뷰] SGLang: Efficient Execution of Structured Language Model Programs](https://cdn.bytez.com/mobilePapers/v2/neurips/94872/images/20-0.png)
![[논문리뷰] Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality](https://icml.cc/media/PosterPDFs/ICML%202024/32613.png)
![[논문리뷰] KIMI K2: OPEN AGENTIC INTELLIGENCE](https://github.com/MoonshotAI/Kimi-K2/raw/main/figures/kimi-logo.png)
![[논문리뷰] Qwen3 Technical Report](https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/logo_qwen3.png)
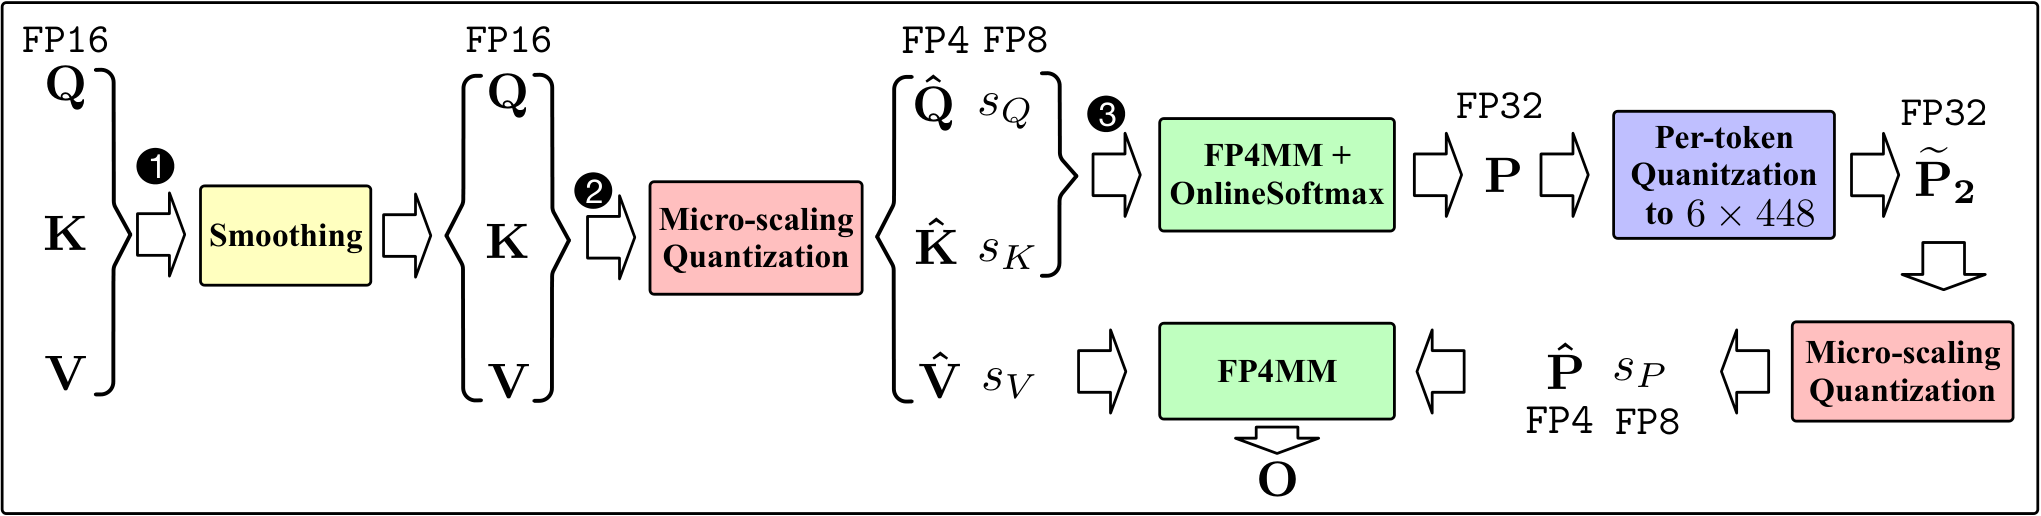
![[논문리뷰] SageAttention3: Microscaling FP4 Attention for Inference and An Exploration of 8-bit Training](/assets/images/papers/2505.11594/figure-2.png)
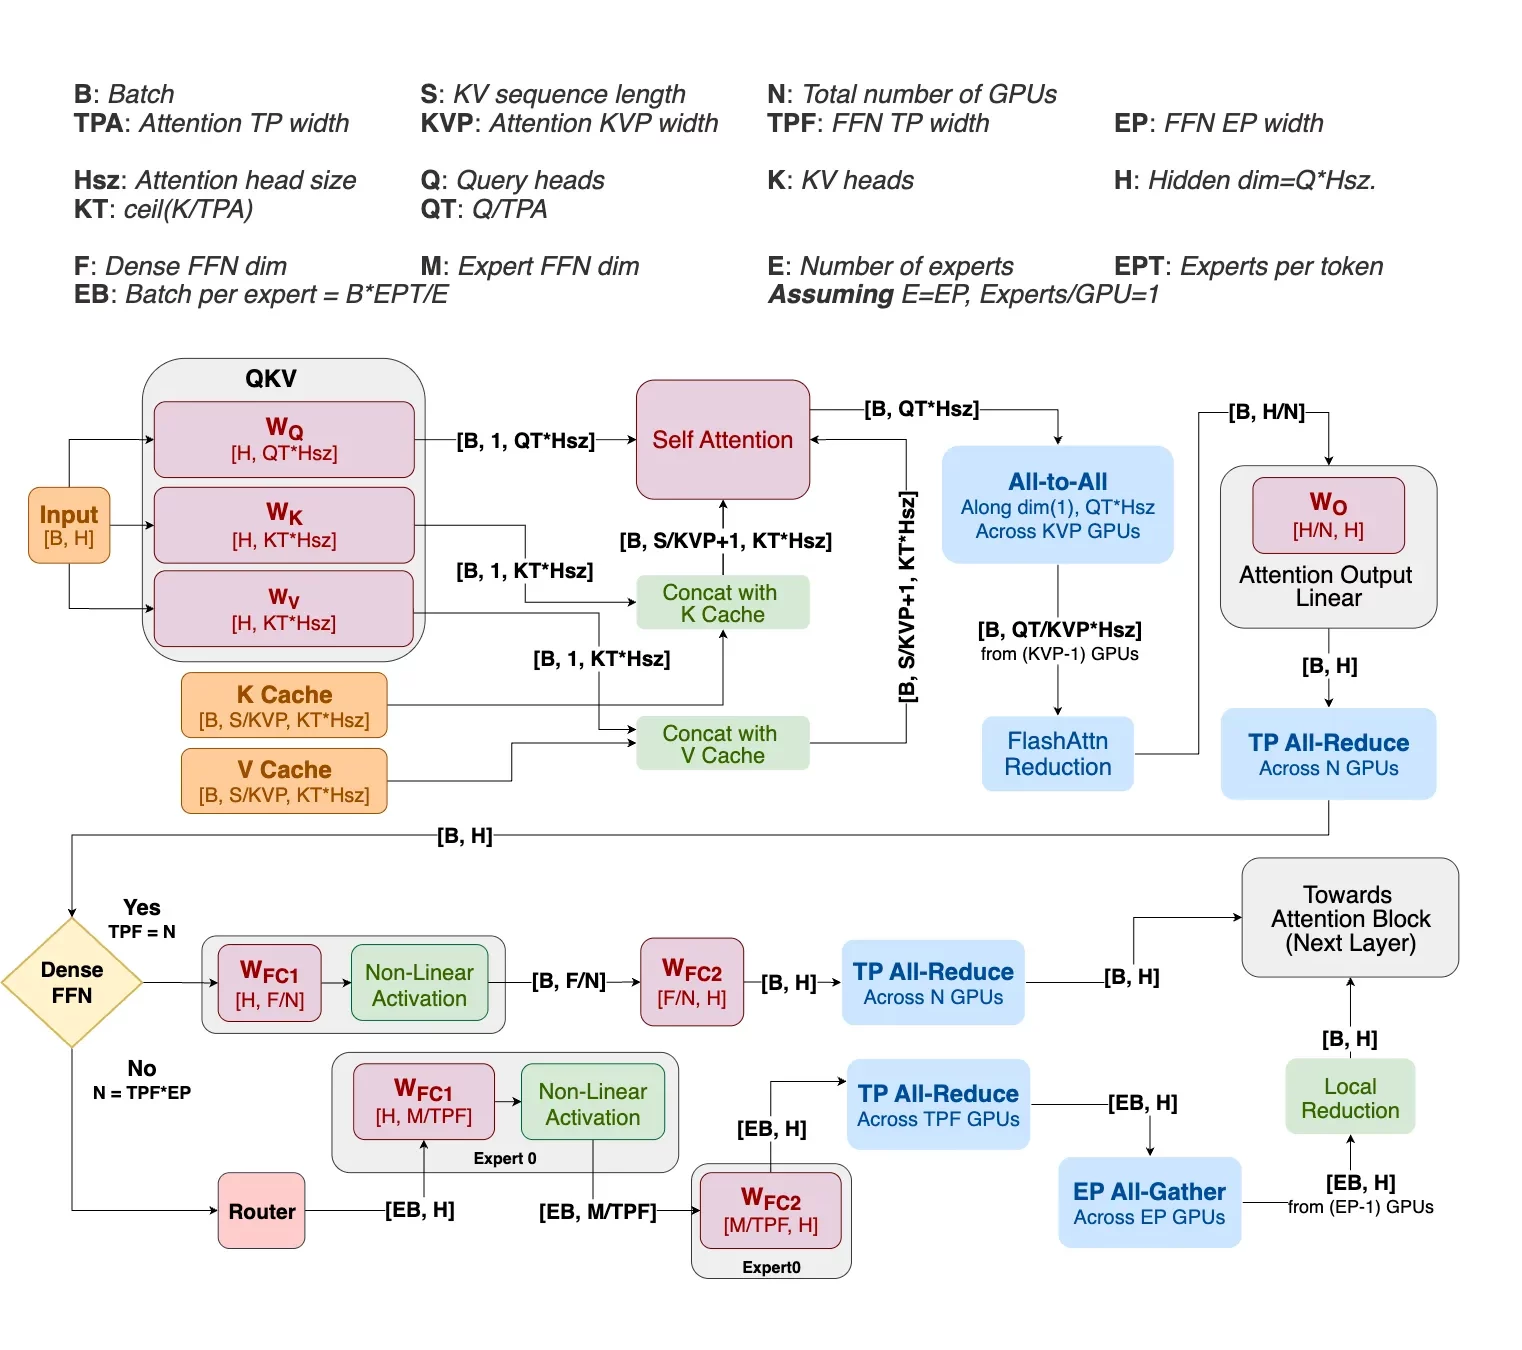
![[논문리뷰] Helix Parallelism: Rethinking Sharding Strategies for Interactive Multi-Million-Token LLM Decoding](https://www.storagereview.com/wp-content/uploads/2025/07/image2-2-png-e1752234784623.webp)